October 23, 2026
AI Model Evaluation Workflow Guide: From Build to Monitor
Your labeling platform is already an AI model evaluation workflow with a different input. Here is the six-step loop, and the evidence for why teams break it.
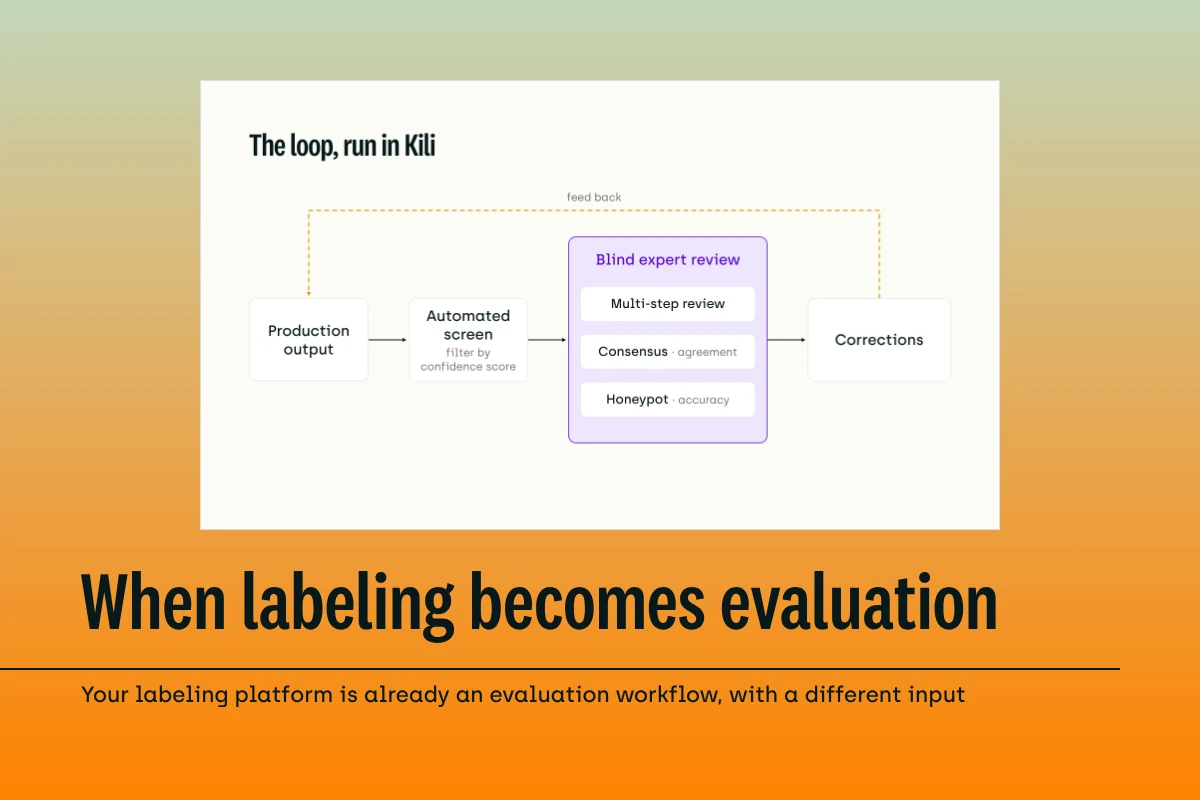
Your labeling platform is already an AI model evaluation workflow with a different input. Here is the six-step loop, and the evidence for why teams break it.
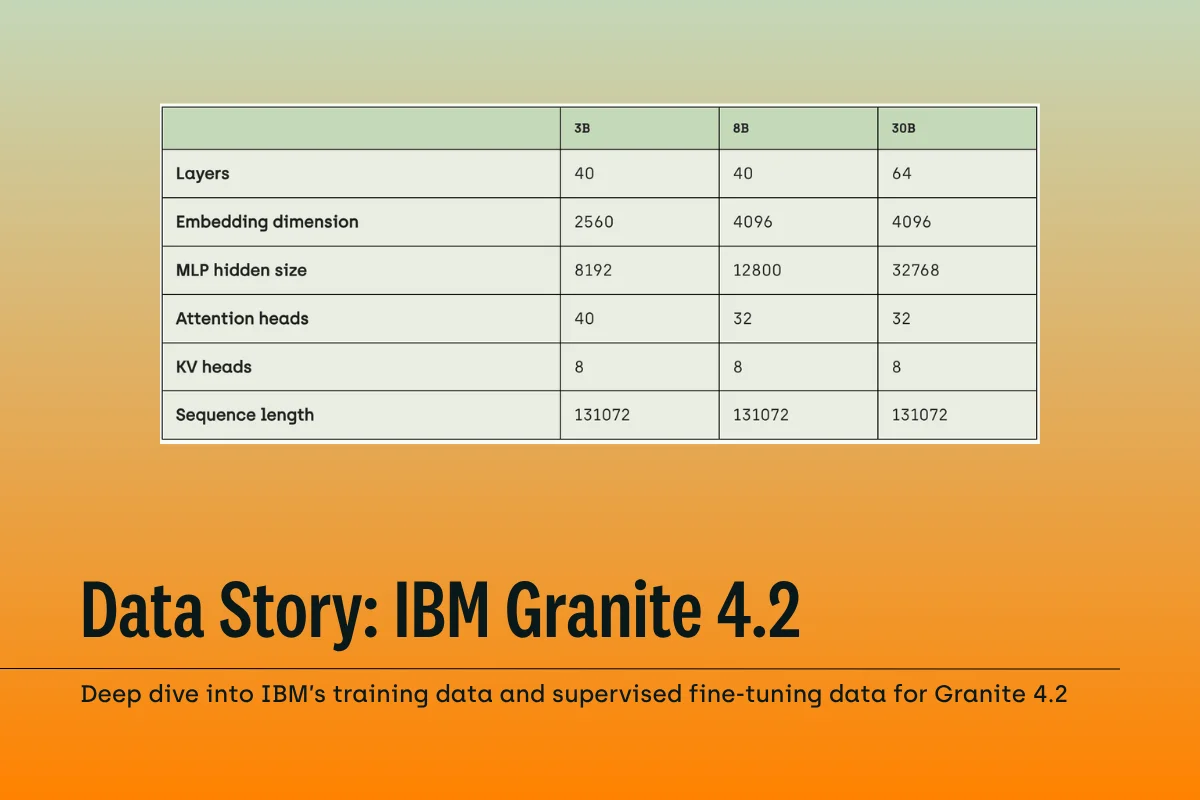
A stage-by-stage record of Granite 4.2 training data, from pretraining phases to reinforcement learning. Every figure carries the IBM document it came from.
Audio annotation turns recordings into verified ground truth for speech AI. This guide covers the types, process, costs, quality control and EU AI Act rules.
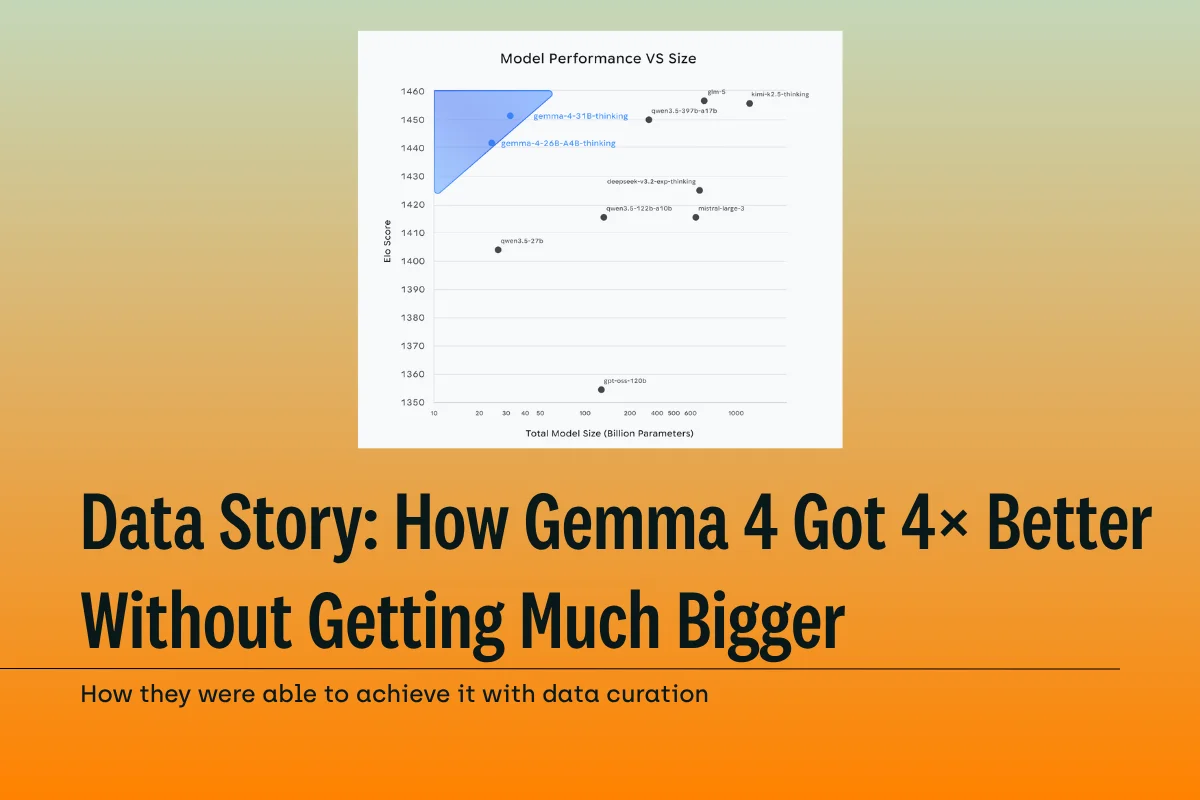
Gemma 4 added 4B parameters over Gemma 3 and quadrupled its AIME score. The technical report credits data composition for the gain, then describes its training data in two sentences.
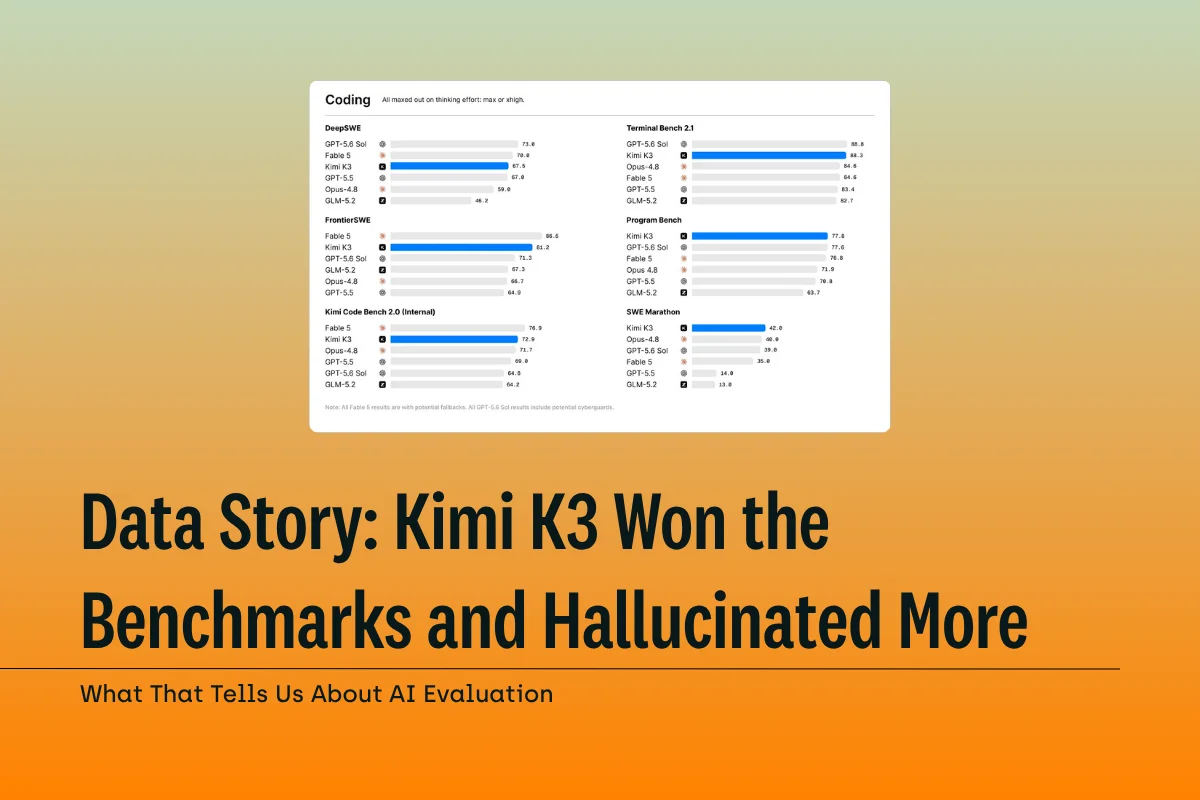
Kimi K3 ranked third on the AI Intelligence Index while its hallucination rate hit 51%. Here is what that paradox reveals about how the industry evaluates models.
AI hallucinations remain one of the biggest reliability problems in large language models. Most training data tells an AI model what to get right. Hallucination-resistant training data also shows it what to get wrong — on purpose.