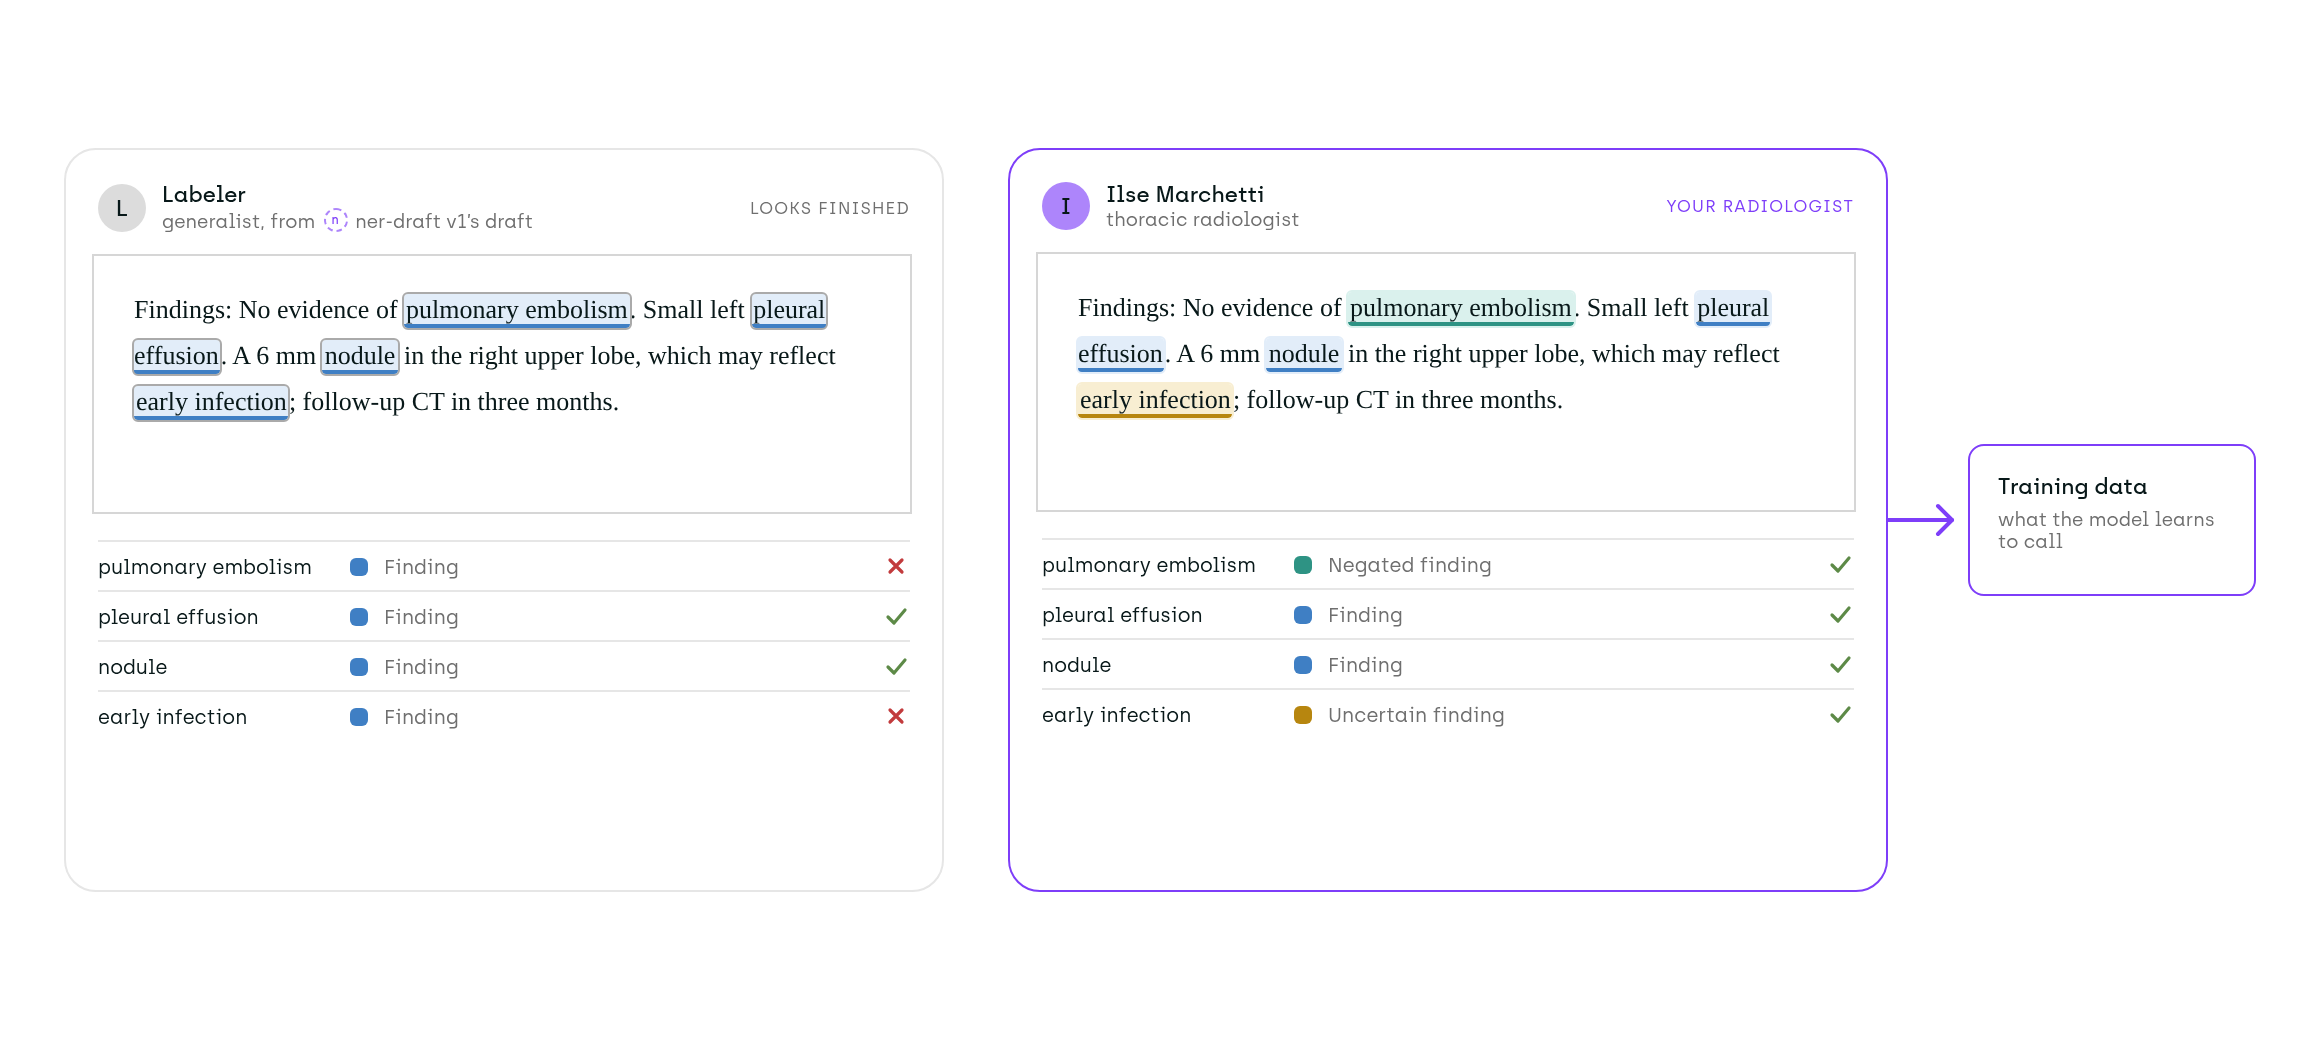
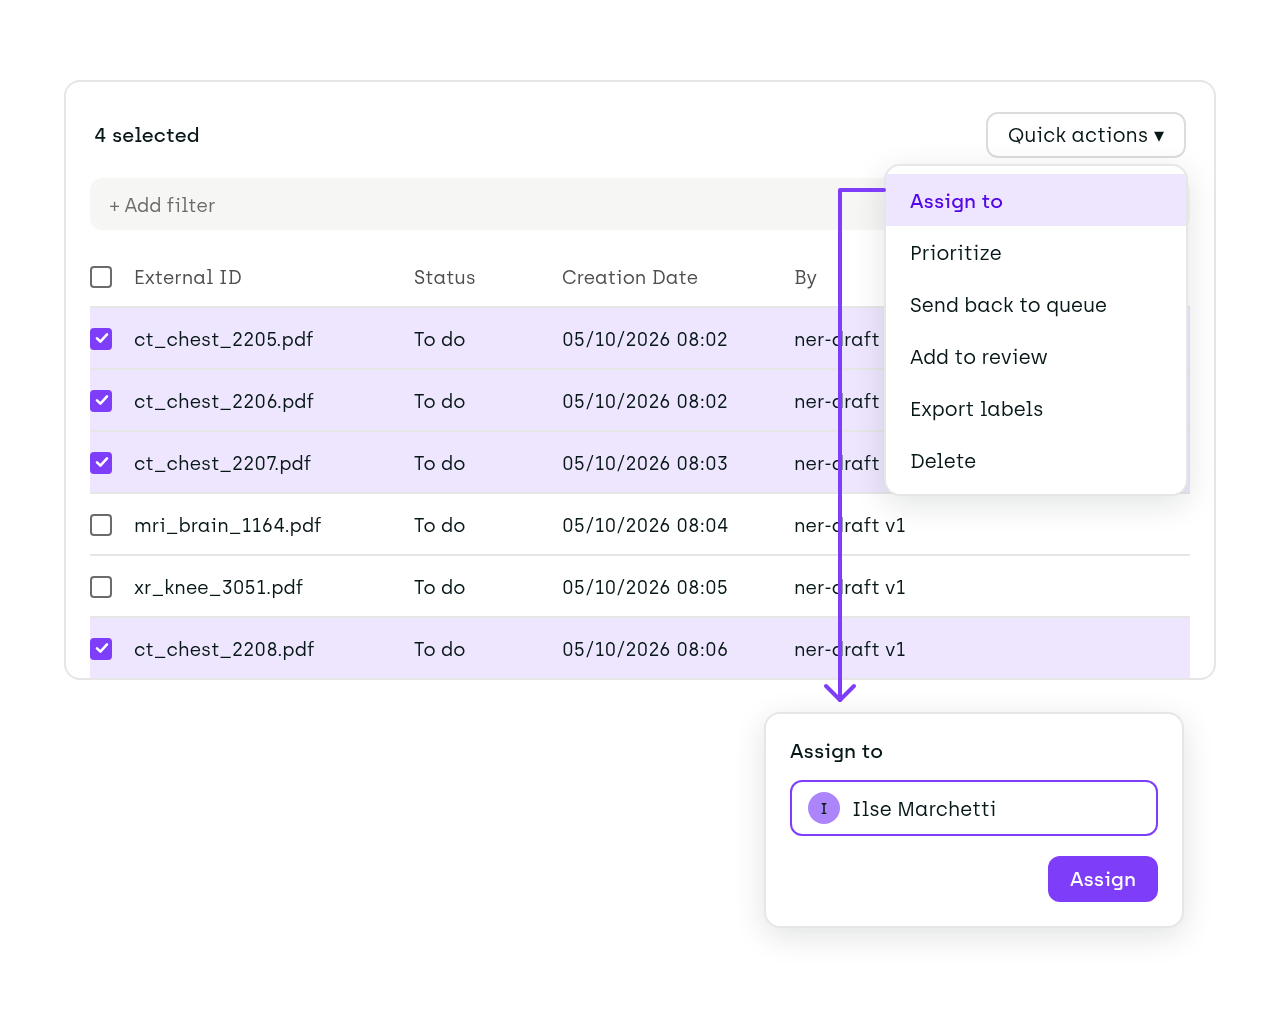
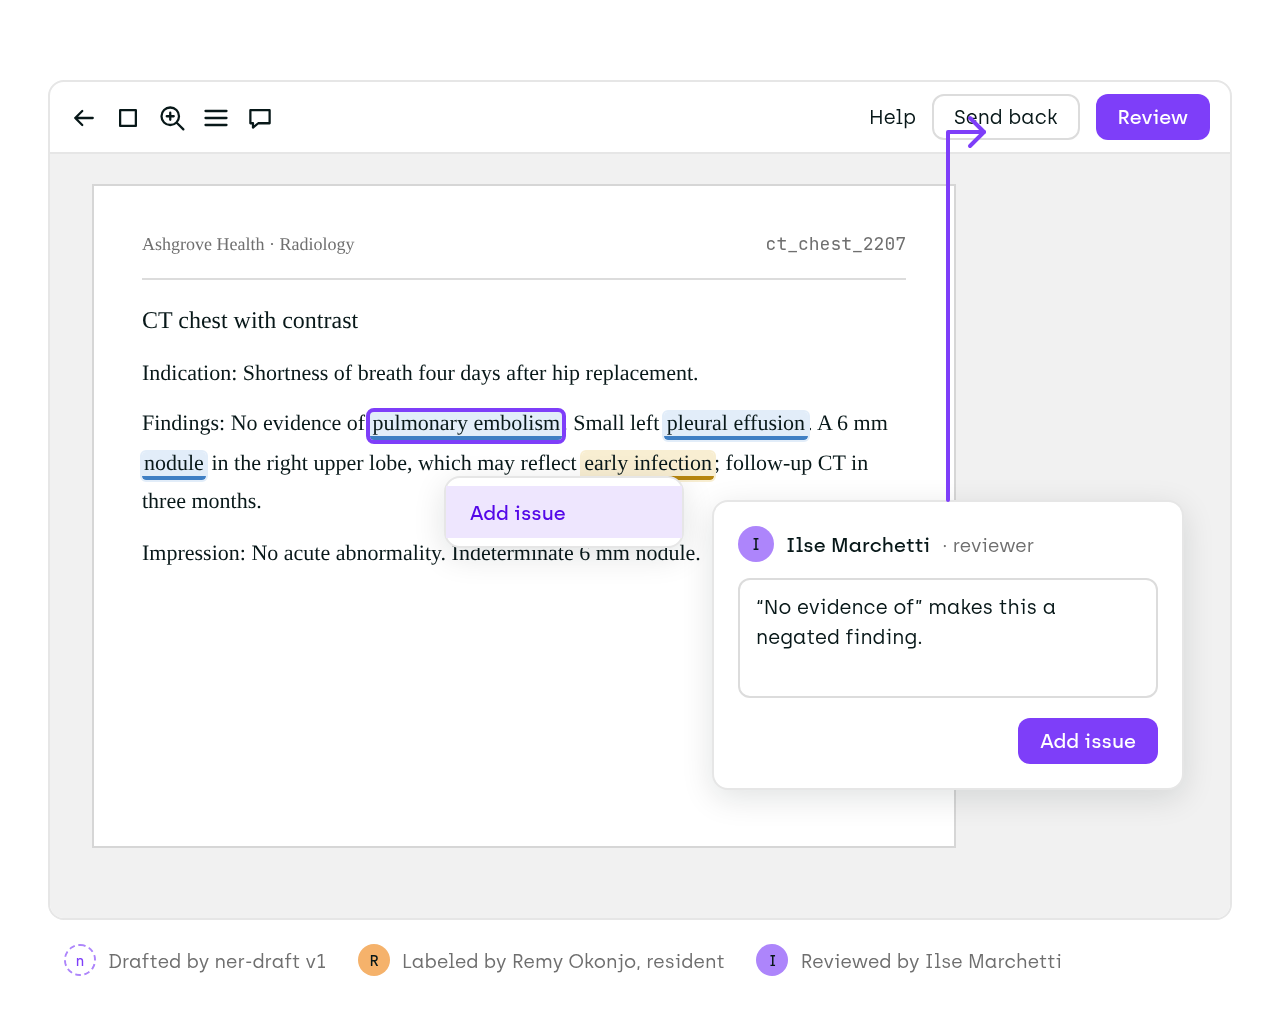
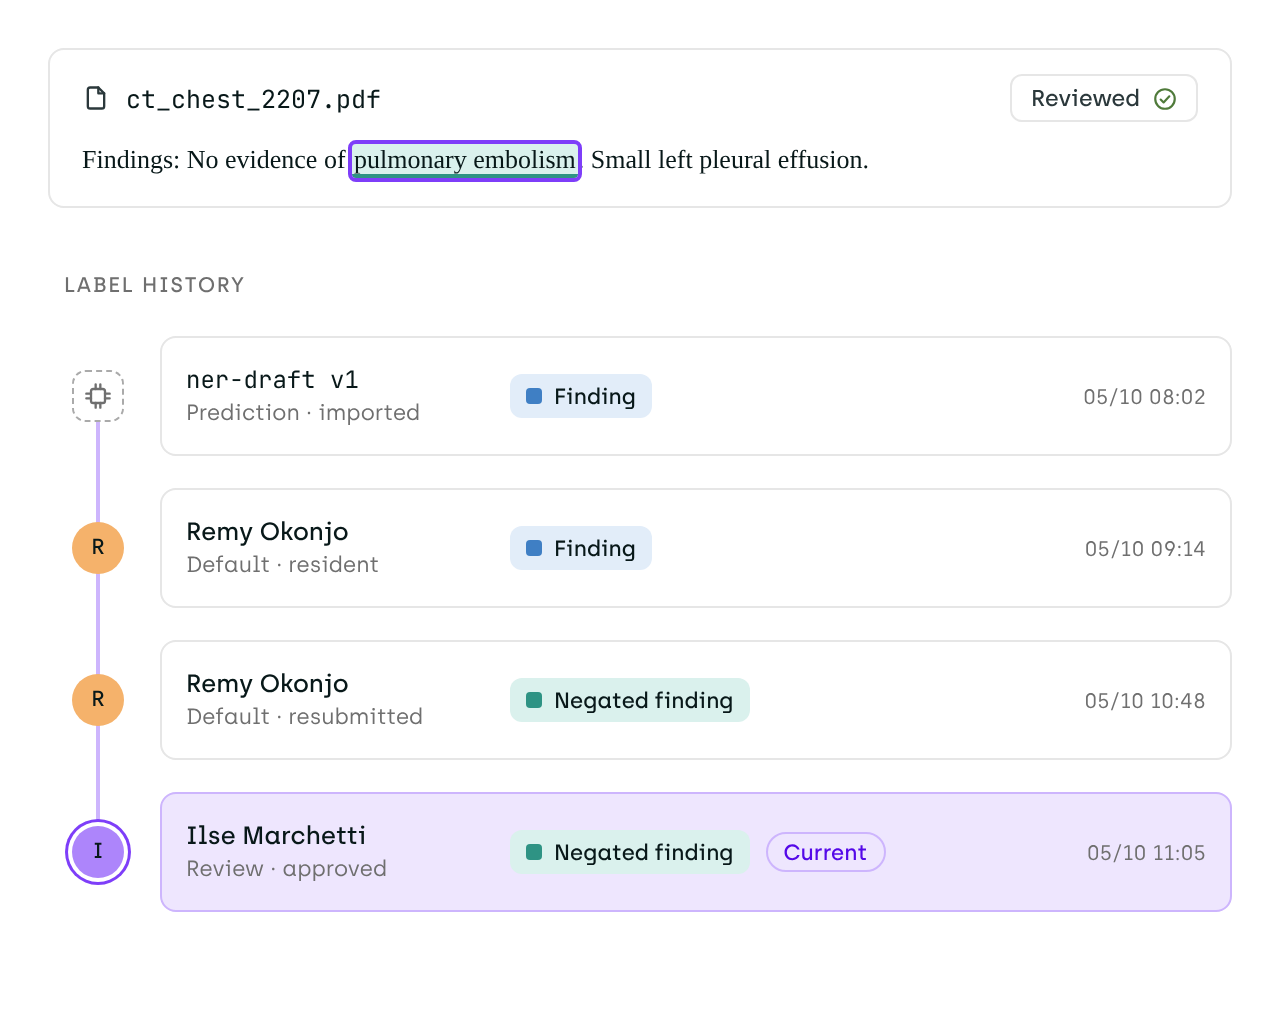
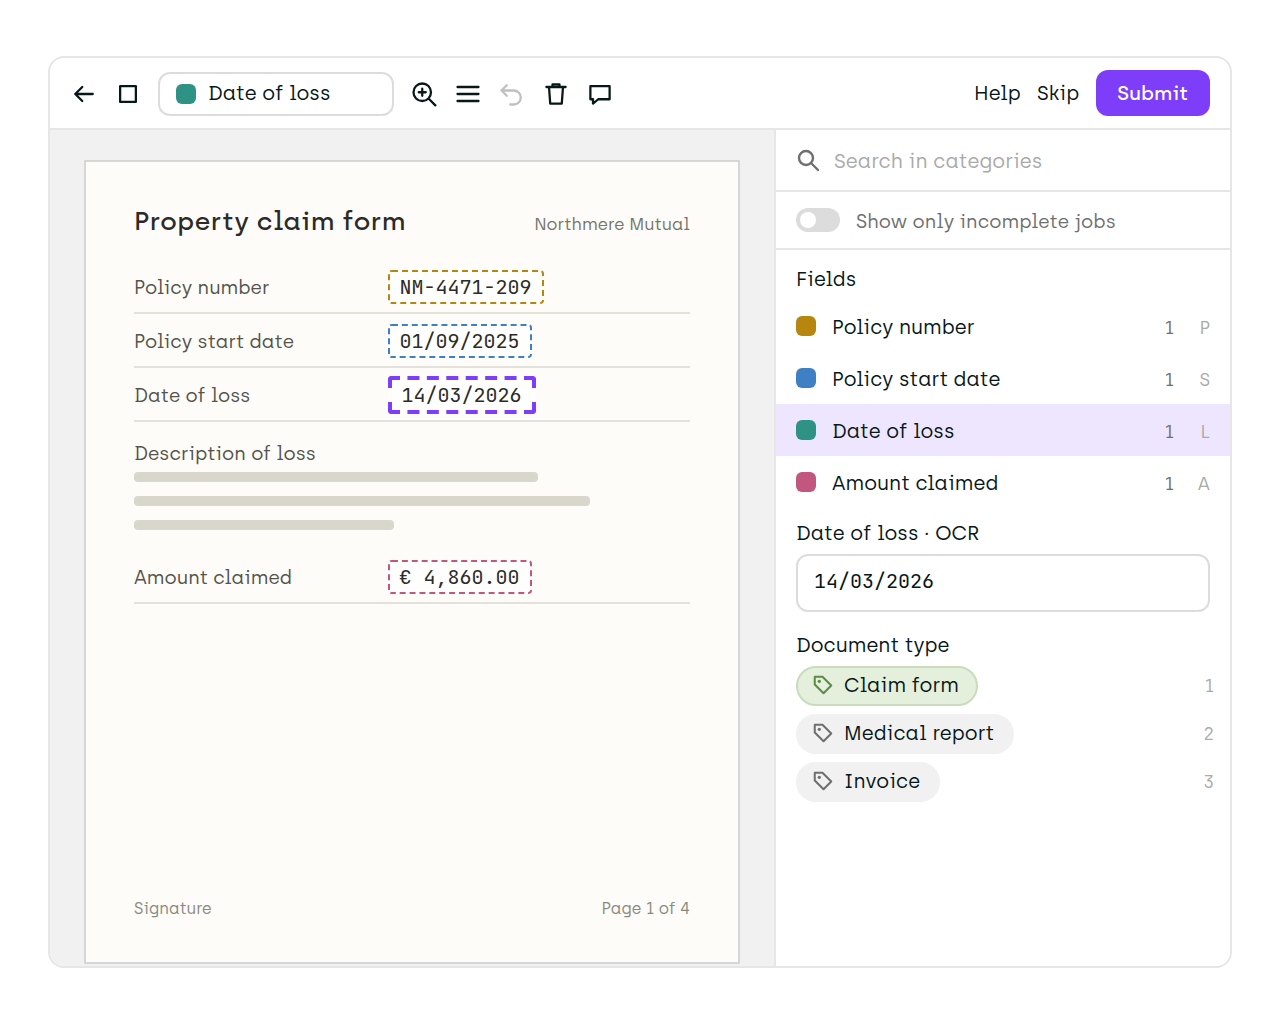
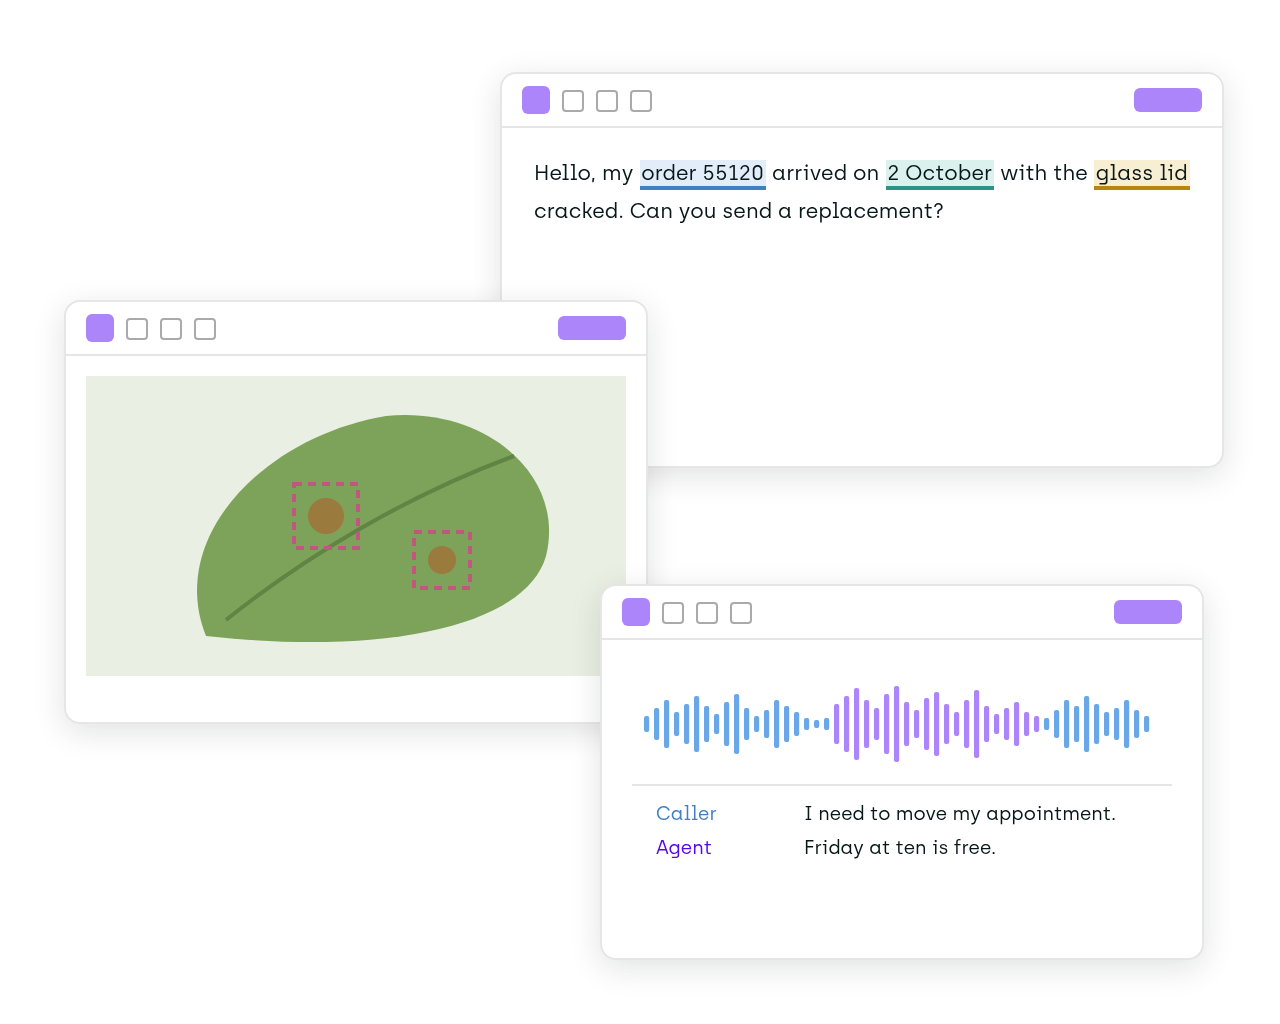
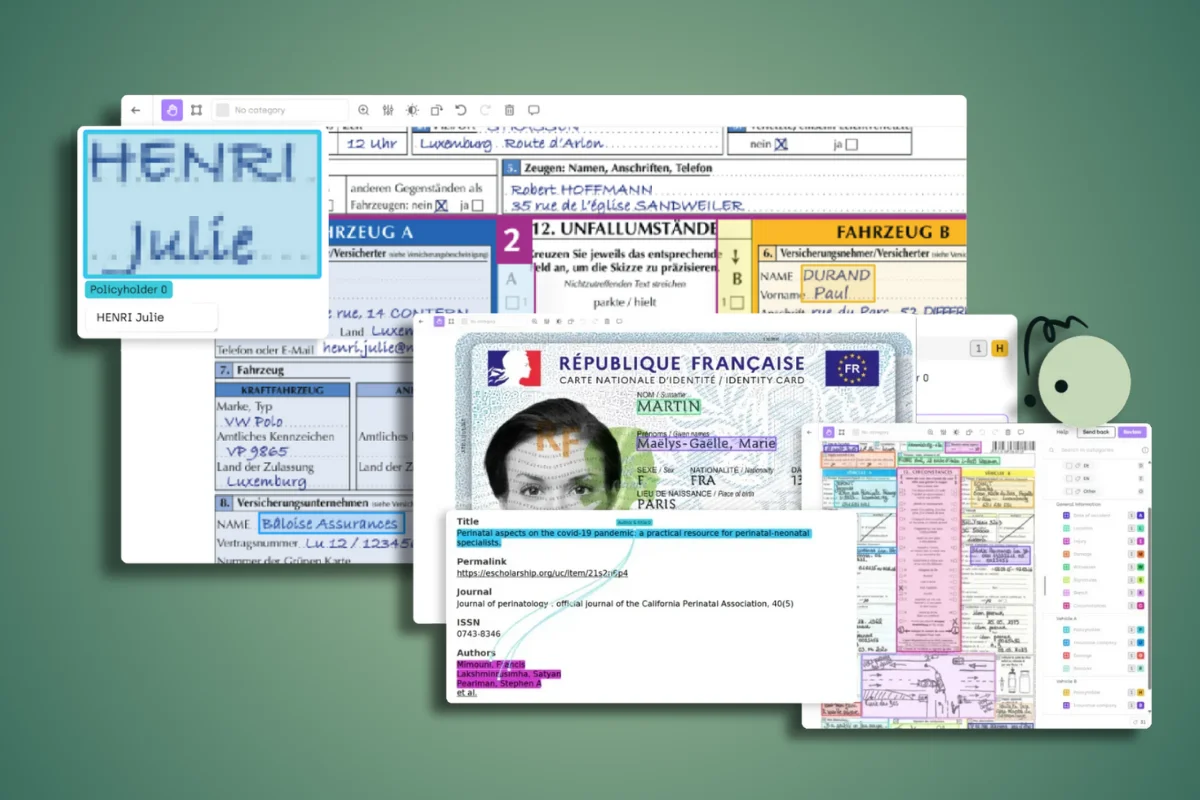
Labeling documents for intelligent document processing (IDP) means marking each field the model should find, reading its value, and recording which document type it came from, on the same kind of scans the model will see in production. In Kili, drawing a bounding box over a field on an image or PDF fills in its text through OCR, entirely in the annotator's browser, and the labeler corrects it where needed. Relation jobs link each value to its field, a classification job records the document type, and consensus on the OCR job shows where specialists read a field differently.