
Industries /
Healthcare
Healthcare AI Evaluation and Post-Training, Led by Your Clinicians
A clinical model can read fluently and still get the dose wrong. Kili puts clinicians in charge of the verdict on summaries, extractions and images, measures how far they agree, and keeps every call on record, with patient data in your storage or on your premises.
ISO/IEC 27001:2022 · SOC 2 Type II · HIPAA compliant
Who's in the loop
The person who holds the clinical knowledge does the judging, in an interface built for review.
- Physicians
- Radiologists
- Pathologists
- Clinical pharmacists
- Medical coders
- Clinical documentation specialists
Use cases
Where healthcare teams use Kili
From checking what a clinical model says, to teaching it what to say, to the labeled data underneath.
AI Evaluation
- Clinical summaries checked against the chart
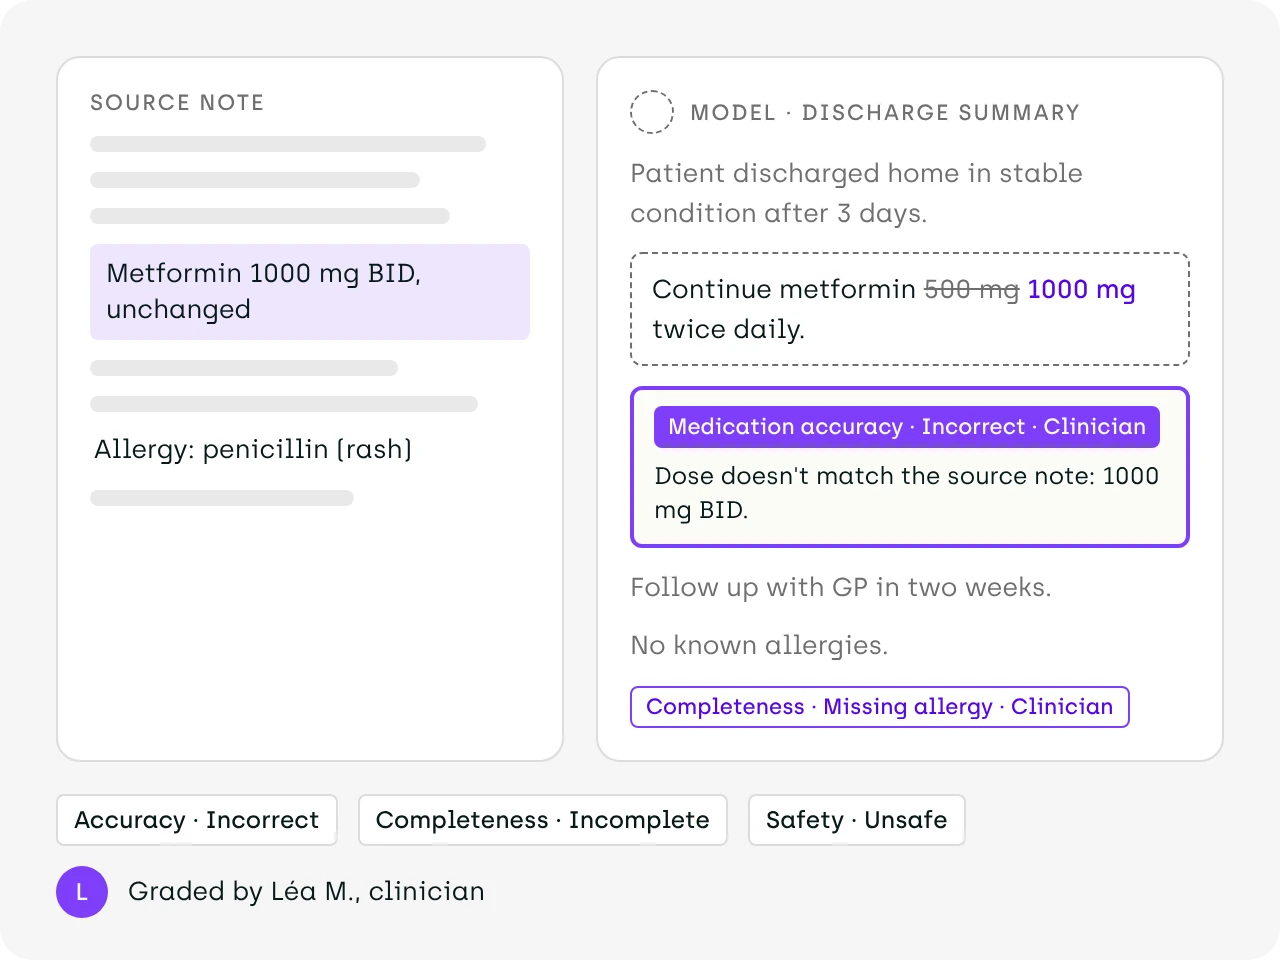
A discharge summary that drops one allergy is worse than no summary. Clinicians see the source notes and the model's summary together and grade each one on accuracy, completeness and safety, with a written reason wherever a grade needs one, so failures are traceable to a cause.
Text · PDF
Learn more → - An LLM judge checked against your physicians
Grading every answer by hand doesn't scale, and an unchecked judge model can't be trusted. Import the judge's verdicts tagged with its model name, have physicians grade a sample of the same answers, and compare the two through the SDK before the judge runs on its own.
LLM-as-a-judge · SDK
Learn more →
Post-Training
- Reference answers written by clinicians
Supervised fine-tuning data is only as good as whoever wrote it. Clinicians write or correct the answers your model should have given, a second clinician reviews each one before it counts, and every revision stays in its label history, ready to export into your training pipeline.
SFT · Text
Learn more → - Preferences ranked by specialists
When two answers are both plausible, the better one is a clinical call. Specialists rank the model's candidate answers and say why, producing preference data for RLHF that reflects how your clinicians actually practice, not how a general annotator guesses they would.
RLHF · LLM (experimental)
Learn more →
Data Labeling
- Medical images segmented by specialists
Segmentation quality decides what an imaging model learns. Radiologists and pathologists outline findings with polygons, segmentation masks and Meta's SAM, consensus shows where readers disagree before the labels reach training, and honeypot cases check each reader against findings you've already confirmed.
Image · Segmentation
Learn more → - Clinical entities extracted from notes and letters
Referral letters and lab reports bury the facts a model needs. Coders and clinicians tag medications, dosages, diagnoses and the relations between them on text and PDF, so the extraction model learns from people who read these documents every day.
NER · Text · PDF
Learn more →
Working on something clinical that isn't listed here?
Tell us about the model, the data and who needs to judge it, and we'll show you how it runs in Kili.
Why Kili
Clinical judgment, measured and on record
Expert-in-the-Loop
Clinician time goes to the calls only clinicians can make
The clinician who holds the knowledge makes the call, not a general annotator working from a guide. Kili removes the work around that call: predictions arrive pre-filled, and criteria and workflows are configured in the product, so nothing waits on engineering.
- Start from the model's answer. Push predictions in with a single click, or programmatically through the SDK or API, so clinicians correct instead of starting from blank.
- Criteria in clinical terms, without code. Accuracy, completeness, safety or any criterion you define, set up as jobs in the ontology, with workflows and assignments configured in the interface.
- Custom logic, written once. Checks that need code run as Python plugins hosted by Kili, triggered on submit or review.
Quality, Built In
Quality built into the work, not checked after it
A reference standard is only as good as the clinicians who built it. Kili measures that while they label, and gives each reviewer the source note beside the model output, so corrections are accurate the first time.
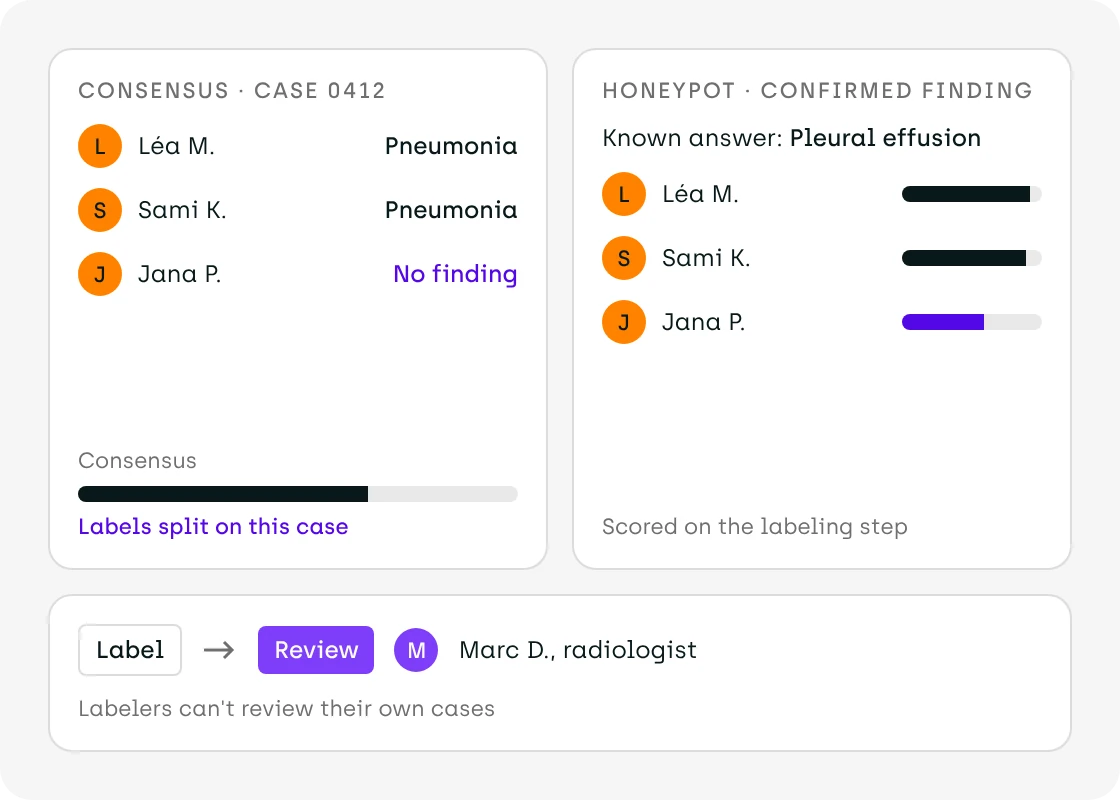
- Consensus. The same case goes to several clinicians, and Kili scores how far their labels match, per case and per clinician.
- Honeypot. Cases with confirmed findings score each clinician against a known answer.
- Multi-step review. Review steps you configure, with step separation so nobody approves their own labels.
Auditable from Day Zero
Quality recorded as the work happens, and kept
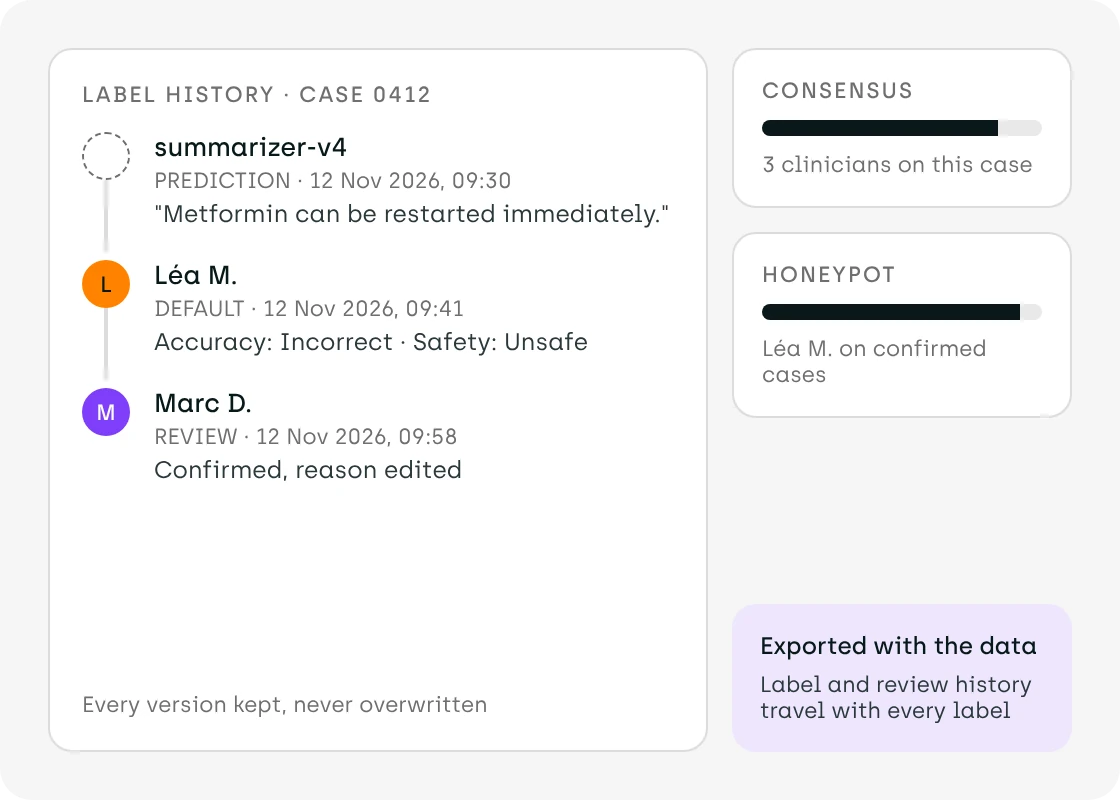
Every quality check leaves a record in the same project that produced the labels. When an auditor asks how your ground truth was built, the answer already exists, and nothing has to be reconstructed.
- Who made each call. Every label version records its author, label type and date.
- How good it was. Consensus and honeypot scores, per case and per clinician.
- Kept and exportable. Versions are never overwritten, and label and review history exports with the data.
Deploy Your Way
Patient data stays where it is
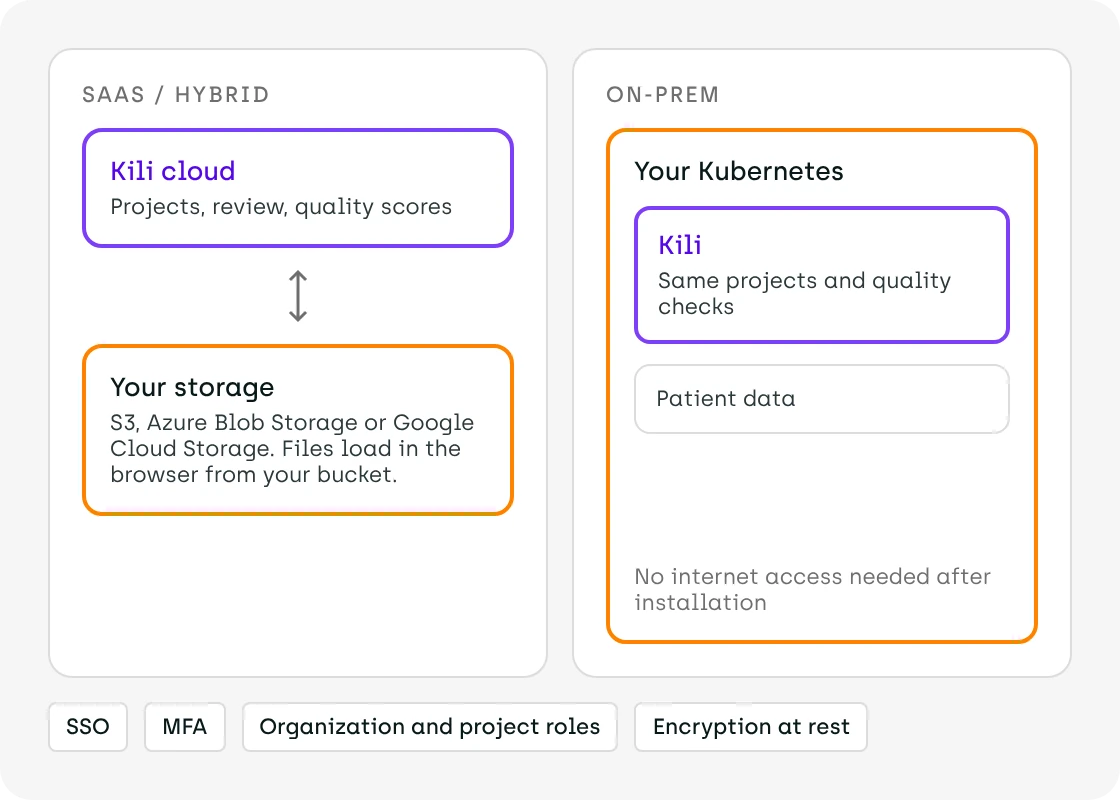
Clinical records don't need to move to be labeled or evaluated. You choose where Kili runs and where patient data lives, and your security team gets the controls and certifications it will ask for.
- SaaS / Hybrid. Use Kili's cloud while patient data stays in your own S3, Azure Blob Storage or Google Cloud Storage bucket, loaded straight into the browser.
- On-Prem. Kili runs on your own Kubernetes, with no internet access needed after installation.
- Controls and certifications. SSO, MFA, organization- and project-level roles and encryption at rest. HIPAA compliant, ISO/IEC 27001:2022 certified and SOC 2 Type II.
Data provenance you can trace, case by case
Kili goes beyond reviewing, correcting and labeling datasets. It keeps the record of how every case was made, so you can trace your data's provenance whenever traceability or a regulatory requirement calls for it.
- Who labeled the data, and with what expertise?
Every label carries its author. Organization- and project-level roles decide who labels and who reviews. - How much did the clinicians vary?
Consensus sends the same case to several clinicians and scores how far their labels match, per job and per clinician. - How was each reader's accuracy checked?
Honeypot cases with confirmed findings score every reader on a workflow step you choose. - Who reviewed the labels?
Multi-step review, with step separation so nobody approves their own work. - Can you show what changed?
Label version history keeps the author, label type and date of every version, never overwritten.
Data types
The formats clinical work comes in
- Text and NLP
Medications, dosages and diagnoses tagged in clinical notes, with the relations between them - PDFs and scanned documents
Referral letters and lab reports: entities on PDFs, OCR on boxes - Image
Findings outlined with boxes, polygons and segmentation with Meta's SAM - Audio
Consultation recordings: segments, speakers and transcription on the waveform - LLM output
Model answers graded, ranked and rewritten by clinicians, in the experimental LLM interface
AI Services Network
More clinical specialists, through Kili's partners
Kili's AI Services Network connects healthcare AI teams with service providers whose clinical specialists already work in the platform.
For healthcare AI teams
Add clinical specialists to your project, at your standard
When evaluation or post-training work outgrows your own clinicians, Kili introduces you to service providers whose medical specialists already work in the platform. They join your project and back your experts' judgment, without changing how the work is checked.
- Matched to the work. Specialists who know your specialty, your languages and your type of task.
- Your criteria, your review steps. They work inside the workflow your clinicians already set up.
- Measured like your own team. Consensus and honeypot score every partner specialist, per case.
For healthcare service providers
Move your healthcare client work onto one platform
If your physicians, medical coders or clinical translators already deliver AI evaluation, post-training or data annotation for healthcare clients, run that work on Kili instead of a different tool for each client, with pricing set up for partners.
- Each client in its own project, with its own members, roles and guidelines.
- Quality you can show every client: review score, consensus and honeypot, from inside their project.
- Deployment to match each contract: SaaS, Hybrid or On-Prem, on a HIPAA compliant platform.
Questions from clinical teams
How do clinicians evaluate medical LLM outputs in Kili?
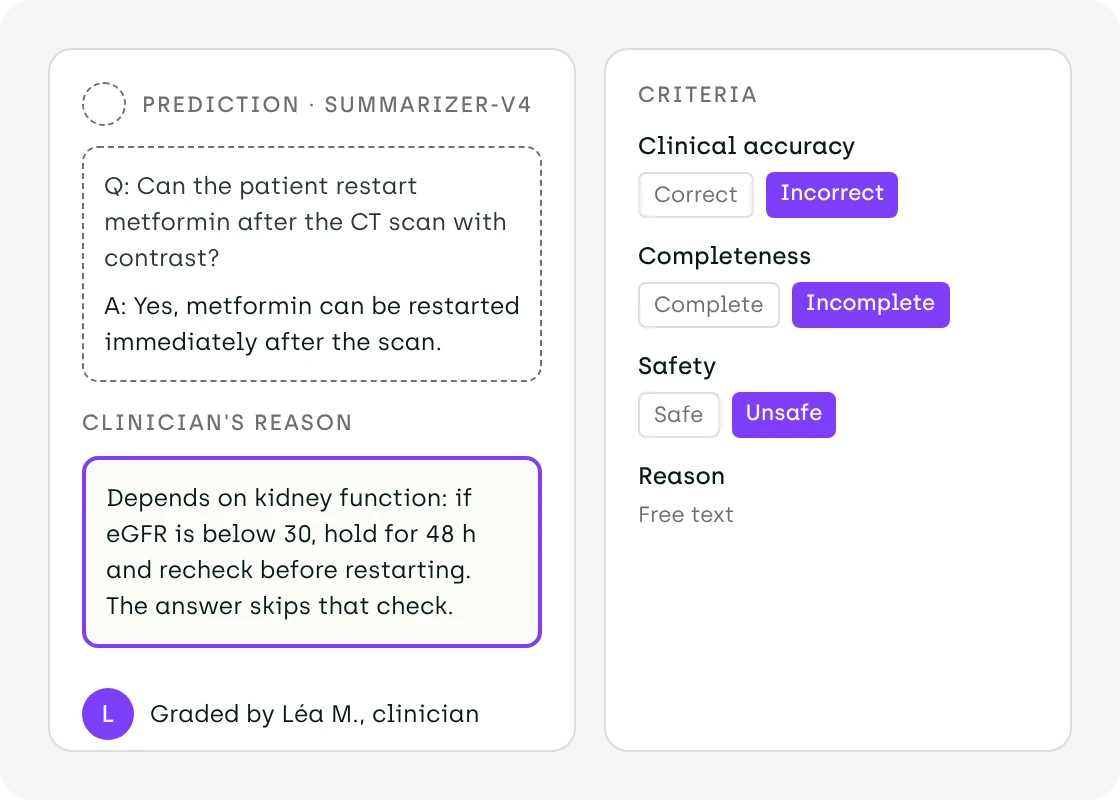
Clinicians evaluate medical LLM outputs by grading each answer against criteria you define, such as clinical accuracy, completeness and safety, with a written reason where a grade needs one. The criteria are set up as classification jobs and the reason as a transcription job, so every grade is structured and comparable across clinicians and model versions.
How do you measure inter-clinician variability?
Inter-clinician variability is measured by sending the same case to several clinicians and comparing their labels. In Kili, consensus does this per job and per labeler, and honeypot cases with confirmed findings score each clinician against a known answer. Both numbers come from the same project that produced the labels.
Can patient data stay in our own environment?
Yes. Patient data can stay in your own AWS S3, Azure Blob Storage or Google Cloud Storage bucket while you use Kili's cloud, with files loaded in the reviewer's browser straight from your storage. Kili can also run entirely on your own Kubernetes cluster, with no internet access needed after installation. Kili is HIPAA compliant.
Can Kili label medical images?
Yes. Radiologists and pathologists can classify images, draw boxes, polygons and segmentation masks, and use Meta's SAM for interactive segmentation. Consensus shows where readers disagree, and honeypot cases with confirmed findings score each reader, so the quality of the labels is measured, not assumed.
What's the difference between clinical evaluation data and post-training data?
Evaluation data measures how a clinical model performs; post-training data changes how it performs. A clinician's verdict that a summary missed an allergy becomes an evaluation label, and the corrected summary becomes post-training data. In Kili, both come from the same kind of project, with the same review steps and quality scores.
Put Your Clinicians' Judgment on Record
Run a full evaluation on your own clinical data, with your clinicians, before you commit.