LCL Bank automates KYC with AI document extraction
Learn how France's LCL Bank transformed regulatory compliance, processing millions of ID documents and DPE forms in weeks instead of months with AI automation.
An LLM or IDP model can pull the wrong value from a contract and look certain doing it. Send the extractions it is unsure of to Kili, where your document specialists check each field against the source page, and get the corrected result back through the API.
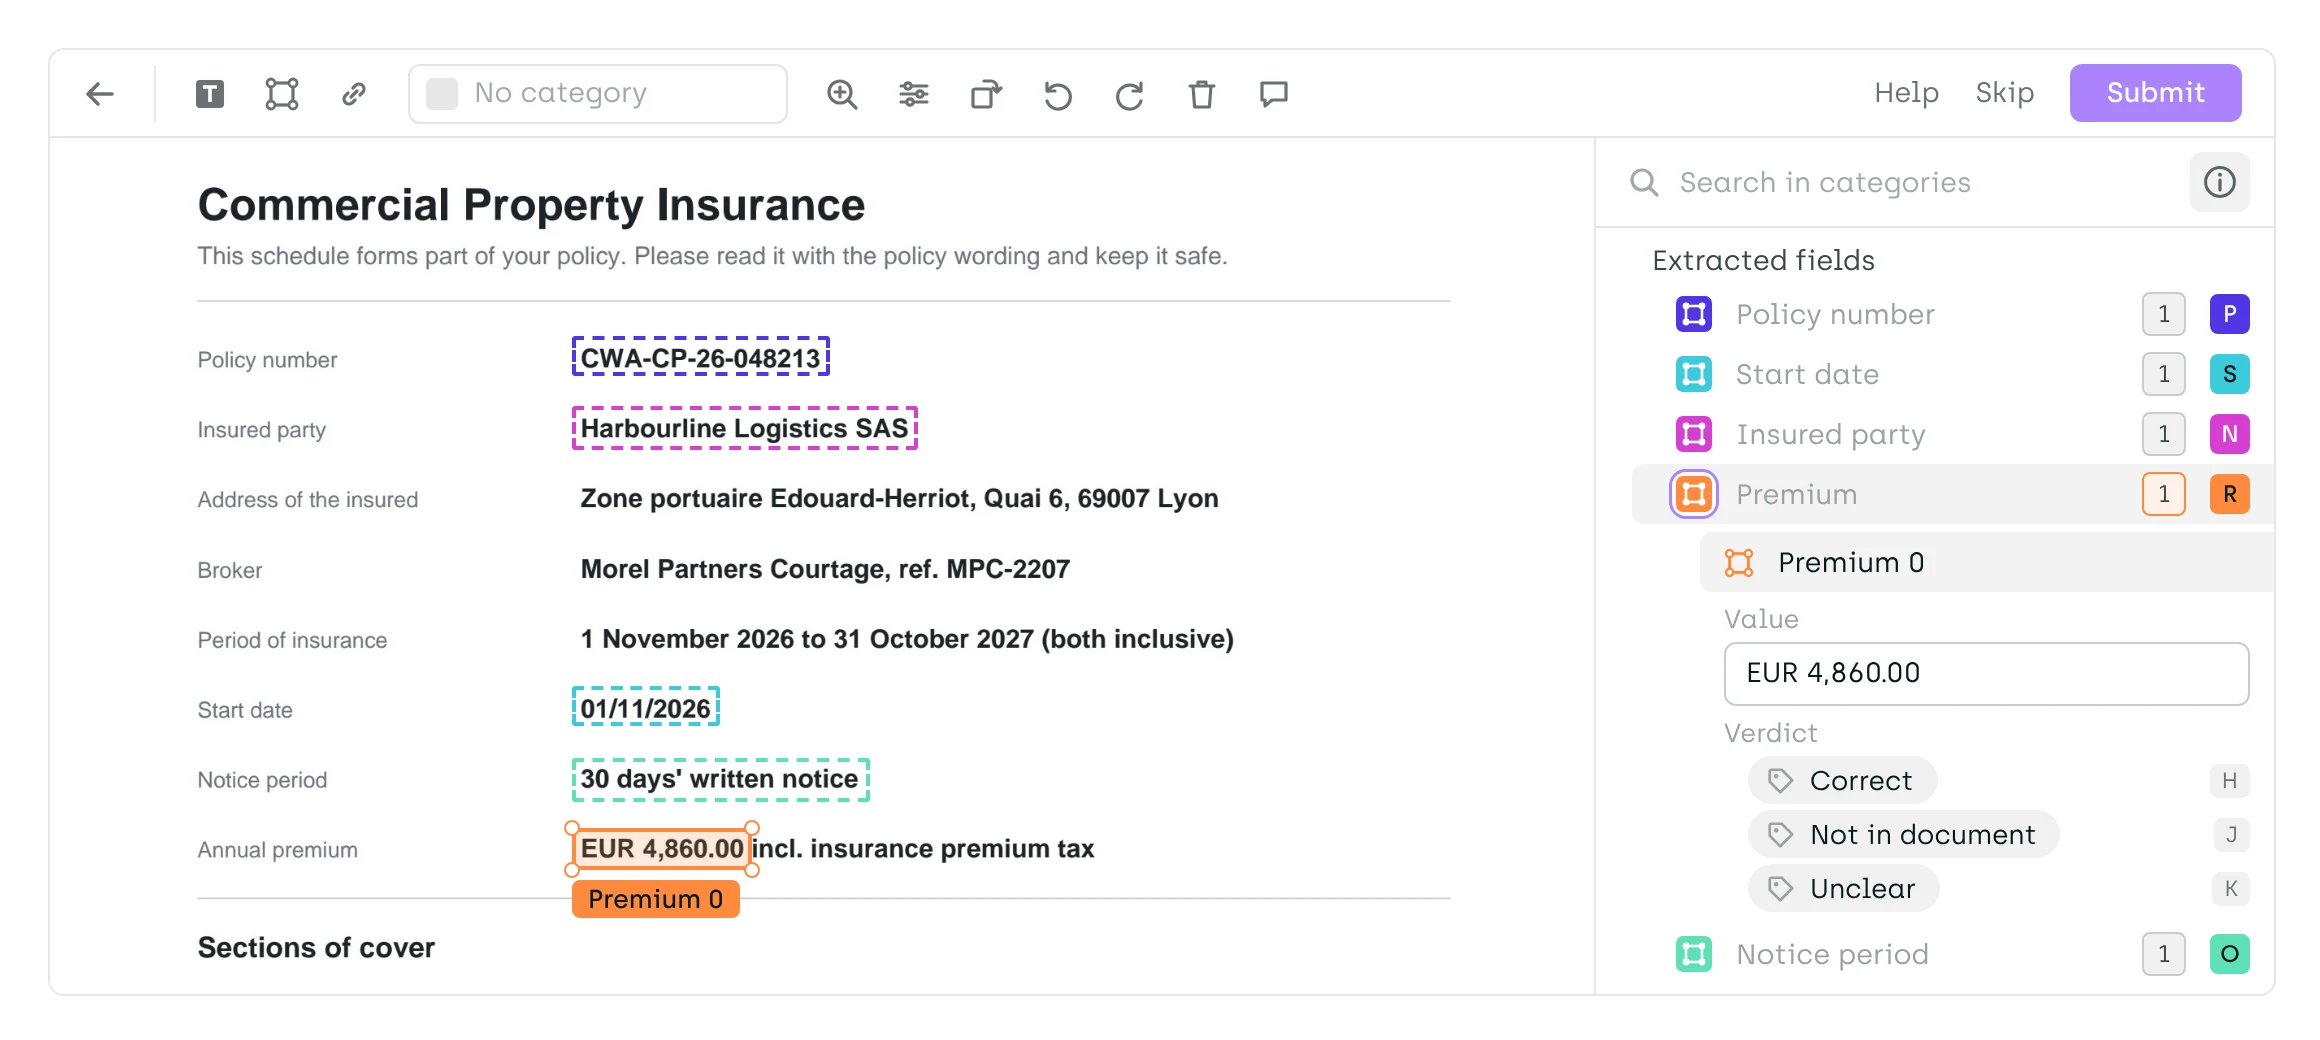
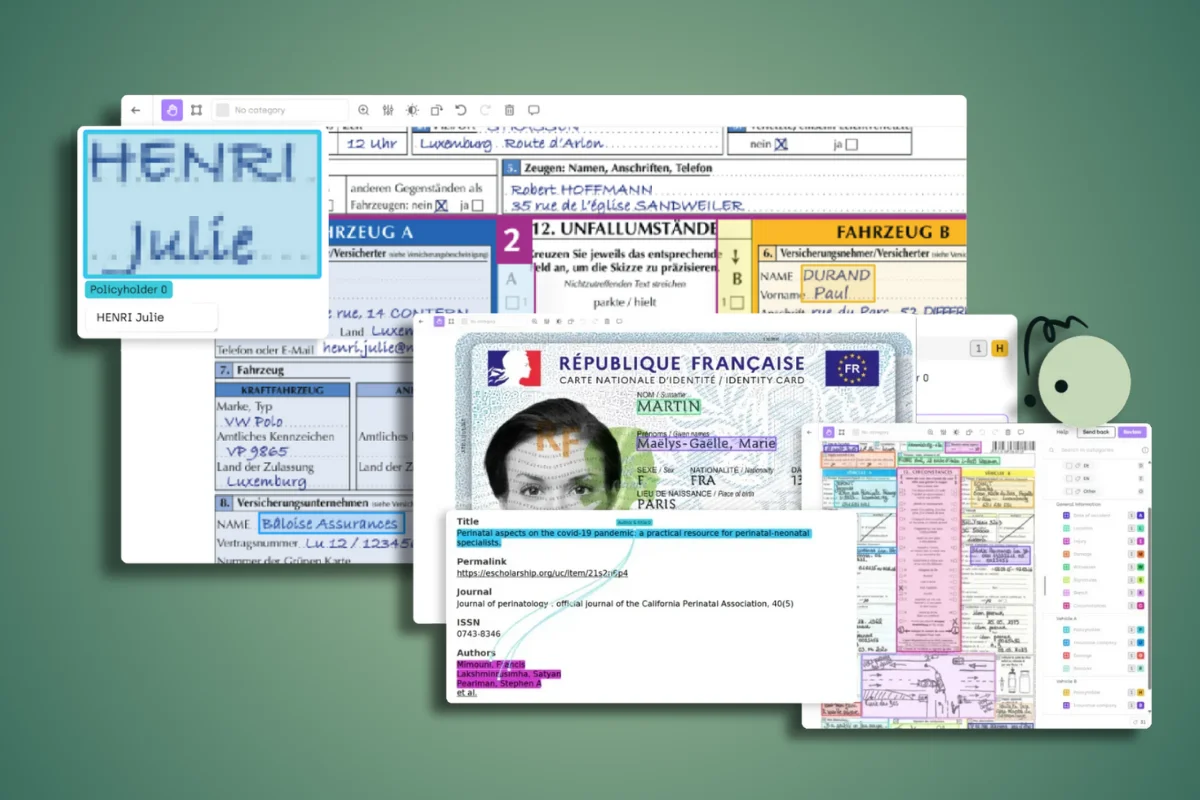
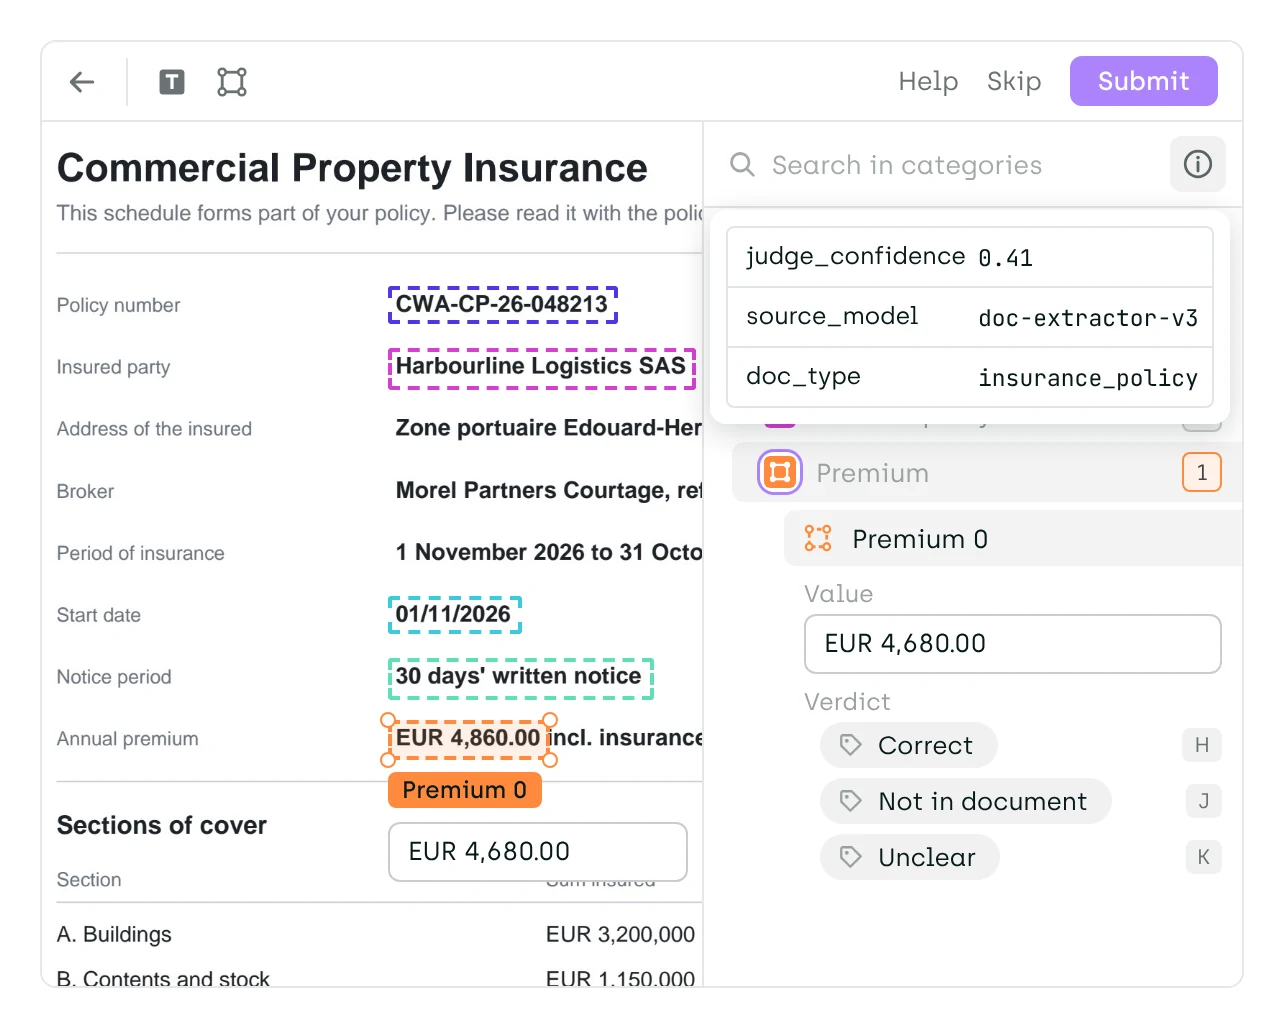
Claims handlers, legal reviewers and clinicians spend their time on the extractions your model is unsure of, not on re-reading whole files. The model's values arrive pre-filled beside the source page, its confidence travels as filterable metadata, and reviewers confirm or correct each field without learning a new tool.
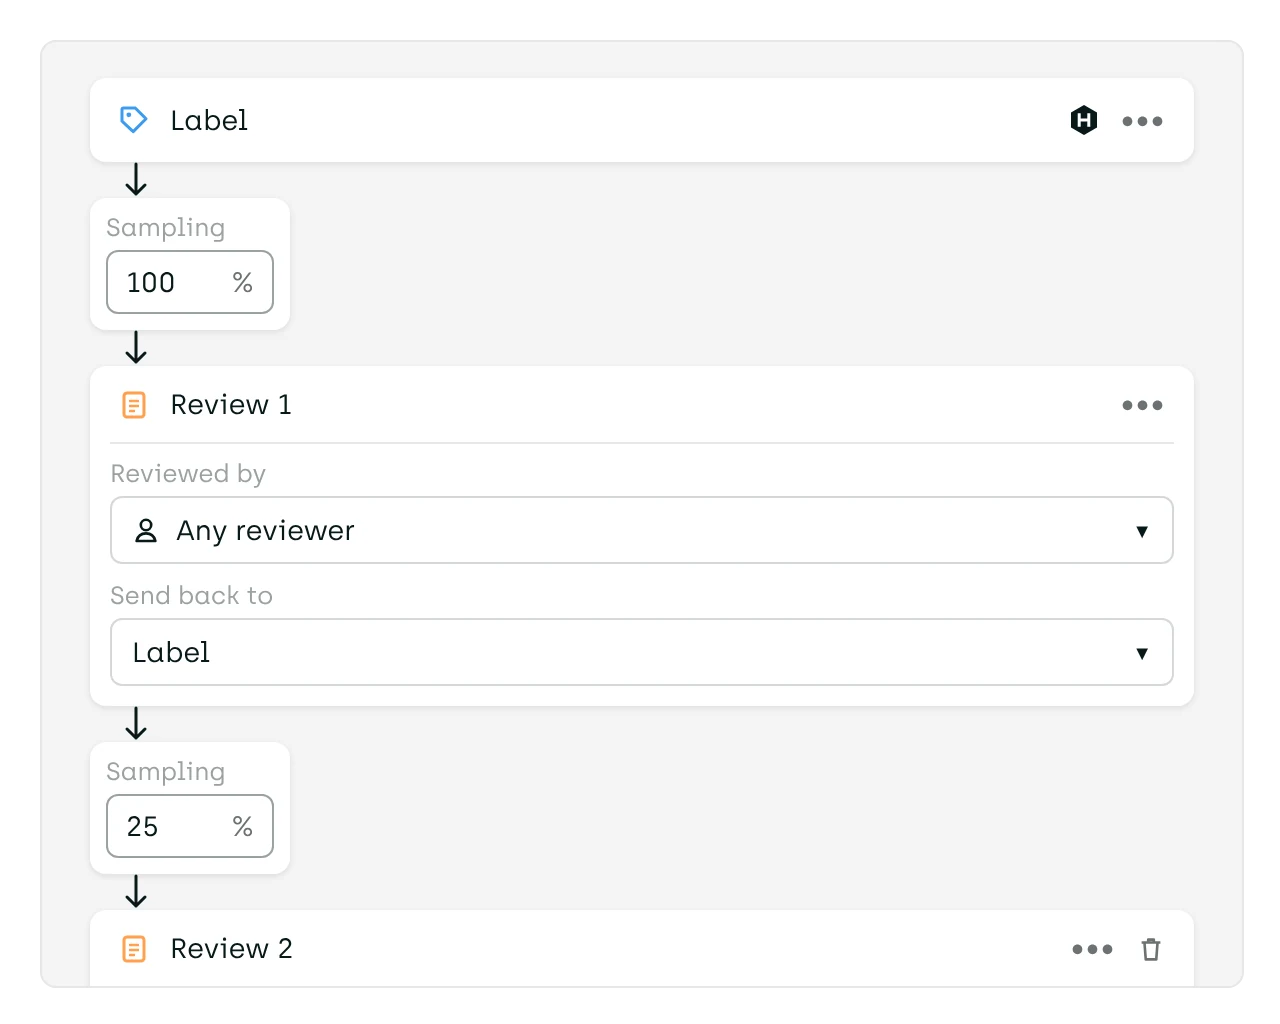
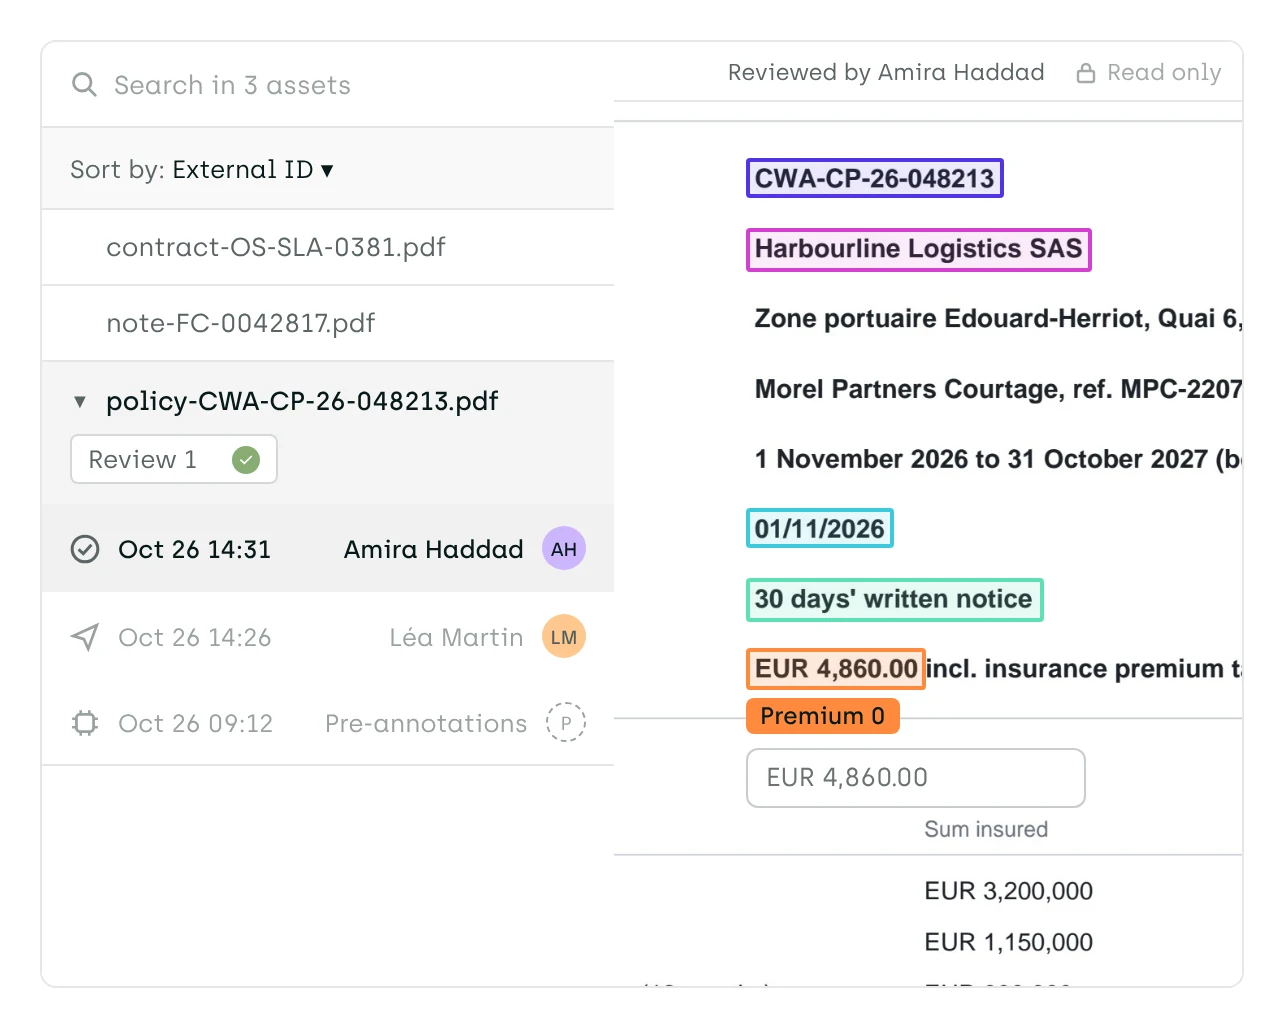
Contracts, invoices, claims files and scanned forms meet the same quality bar, so extraction accuracy doesn't depend on which team handled the file. Each document type keeps its own project and ontology, while Consensus, Honeypot and a second review step show which reviewers, and which fields, need attention.
Contracts, KYC files and patient records stay in storage you control: your own bucket while you use Kili's cloud, or your own Kubernetes, with no internet access needed after installation. Kili is SOC 2 Type II and ISO 27001 certified and HIPAA compliant, and every label version keeps its author, date and time.
Speak to our team for a free 14-day evaluation.
Kili Technology is a complete data suite that supports all data types and handles specialized formats for domain-specific requirements.
Customer stories from the programs that put this to work — with the numbers behind them.
.png)
.png)
.png)
Stay up to date with fresh content from our team — tutorials, use cases, and ideas to help you train AI/ML models better.
Got questions about Kili Technology? Check out our FAQ. If you can't find it in this list, drop a question for our team.
Kili labels PDFs, native or scanned, and images such as PNG and JPEG. Text in a native PDF is read directly; scans and images are read by built-in OCR in the browser. OCR reads English and French by default, and languages can be set per project or per asset. Plain text, rich text and XML documents can be labeled in text projects.
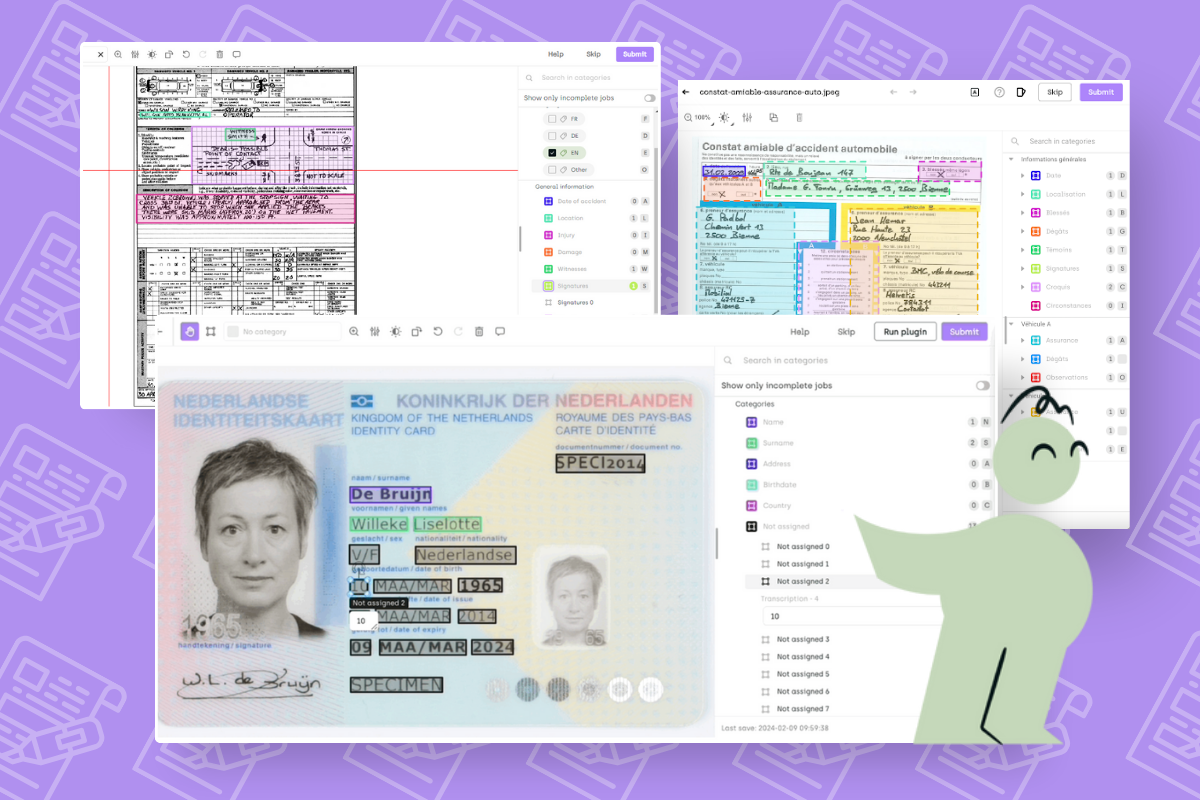
Draw bounding boxes over text regions, tables or form fields and give each box a class from your ontology. An OCR transcription sub-job fills in the text under the box automatically, and classification sub-jobs capture the field type or the reviewer's verdict. Admins set up the ontology per project without code, so each document type can have its own.
Yes. Import the output as predictions through the Python SDK or GraphQL API, tagged with the name of the model that produced it, and reviewers confirm or correct it in place. OCR engine output can also be imported in Google Vision format, so each box matches its text. A confidence score from an LLM-as-a-judge can travel as asset metadata, shown to reviewers and used to filter or prioritize the queue.
Kili builds quality into review rather than checking it afterwards. Consensus sends the same document to several reviewers and scores how closely their transcriptions and classifications match. Honeypot scores each person against documents with known answers. Review steps produce a Review score, and Python plugins check business rules, such as a date format or a total, each time a label is submitted or reviewed.
Kili is SOC 2 Type II and ISO 27001 certified and HIPAA compliant. Documents can stay in your own AWS S3, Azure Blob Storage or Google Cloud Storage bucket while you use Kili's cloud, or Kili can run on your own Kubernetes cluster with no internet access needed after installation. Organization and project roles, Google or GitHub single sign-on and MFA, encryption at rest and label history apply on every project.
Each document type runs as its own project, with its own ontology, reviewers and review steps, and assets arrive through the API as your pipeline produces them. Within a project, asset priority decides what reviewers see first and metadata filters narrow the queue to uncertain or urgent cases. Reviewed labels leave through the SDK or API, and the analytics page tracks labeling and review throughput by day, week and month.