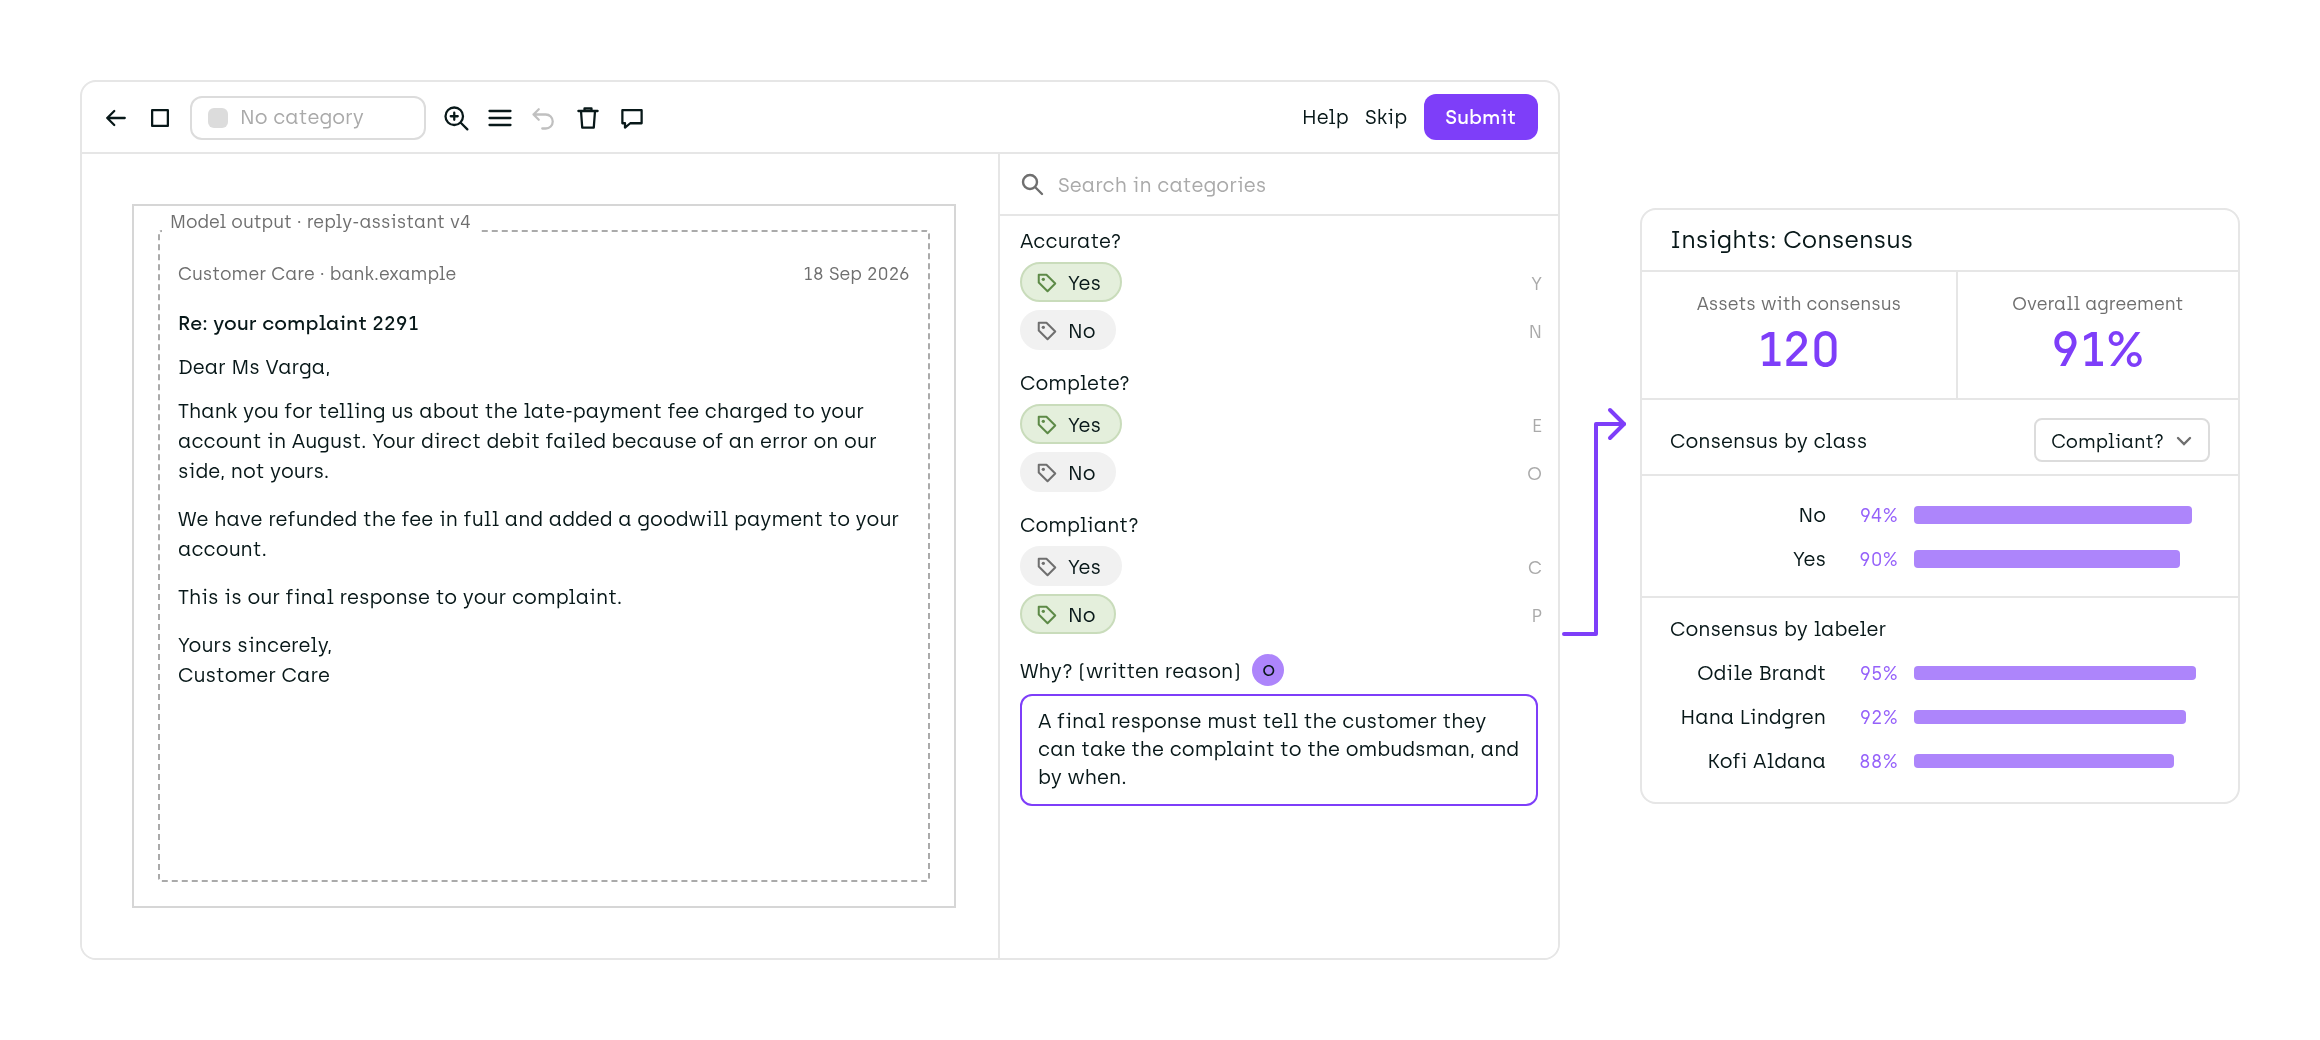
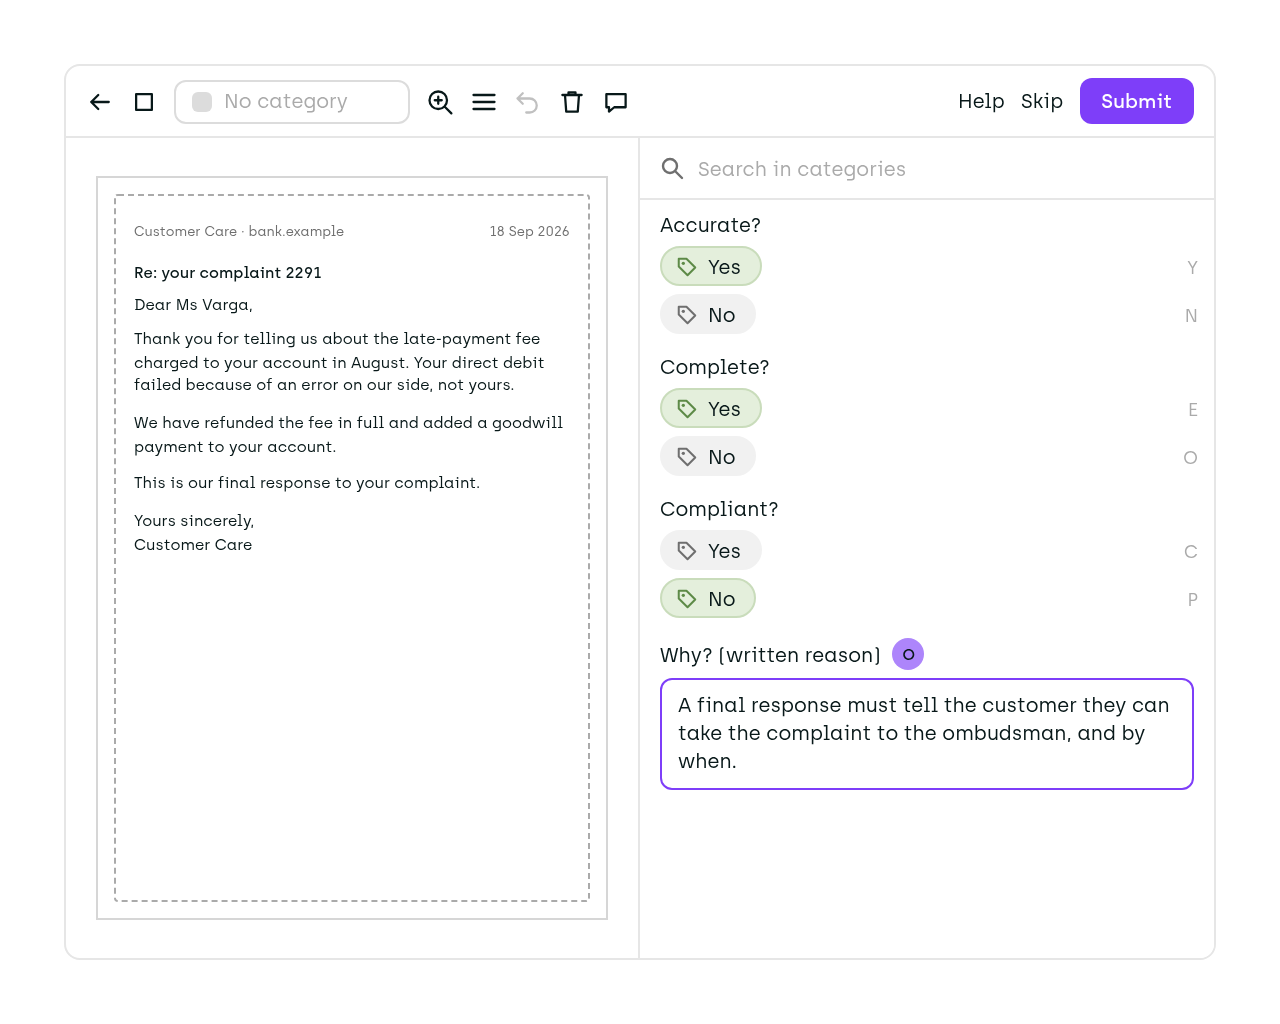
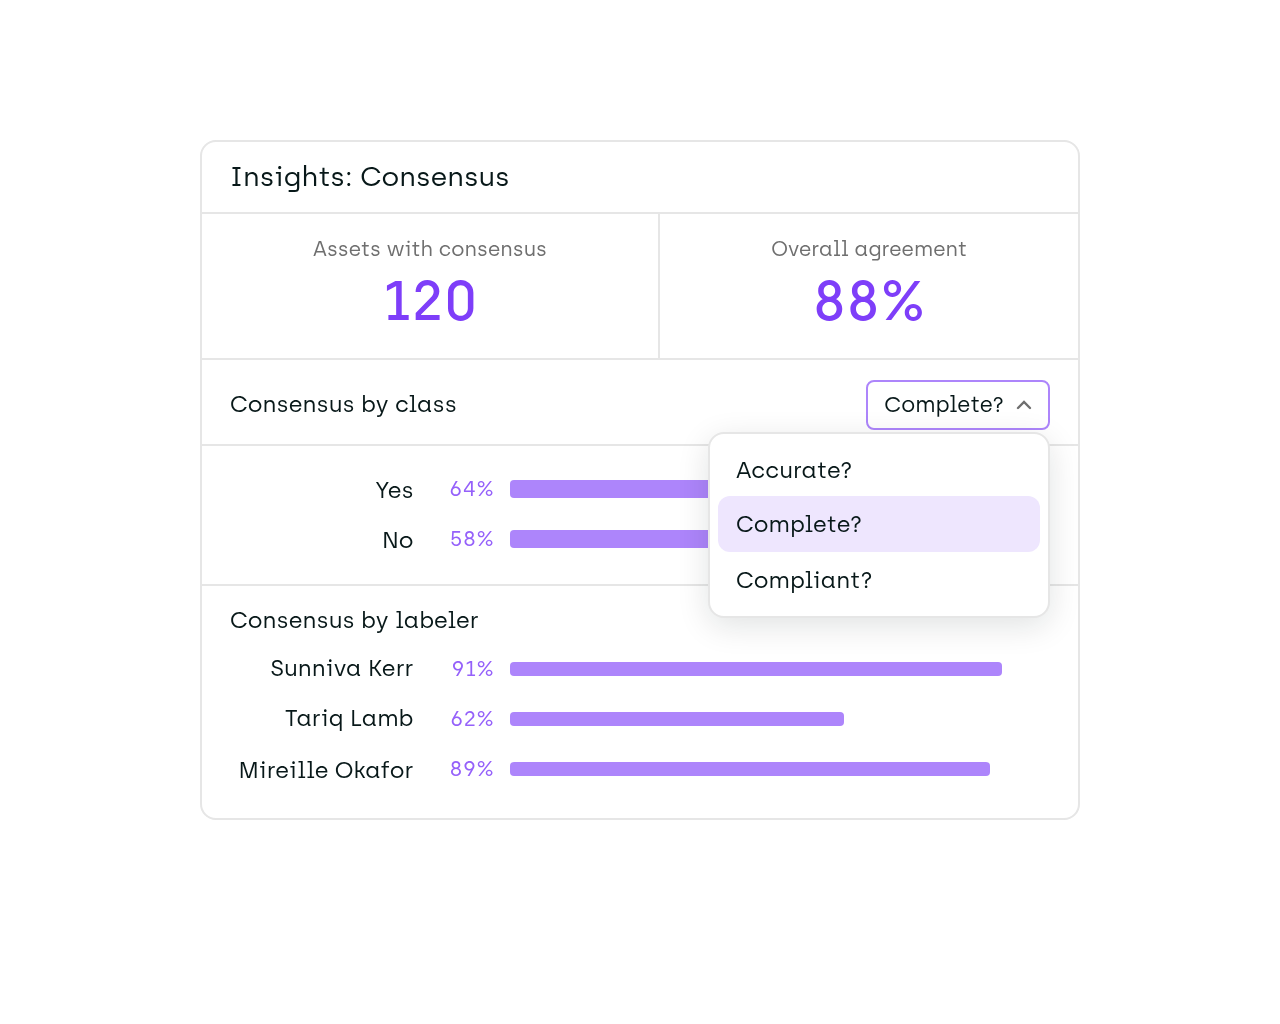
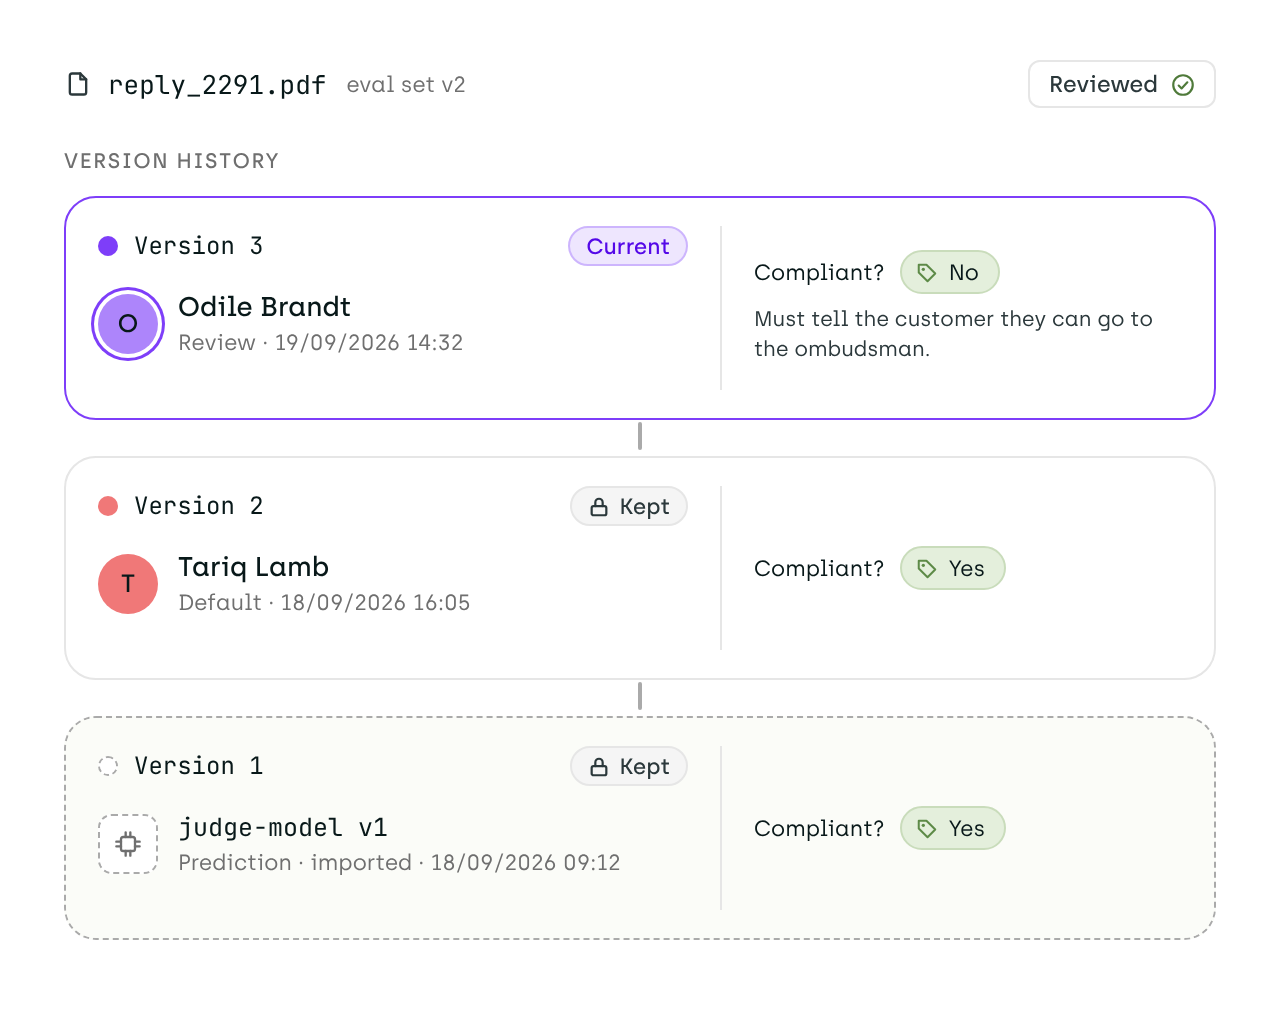
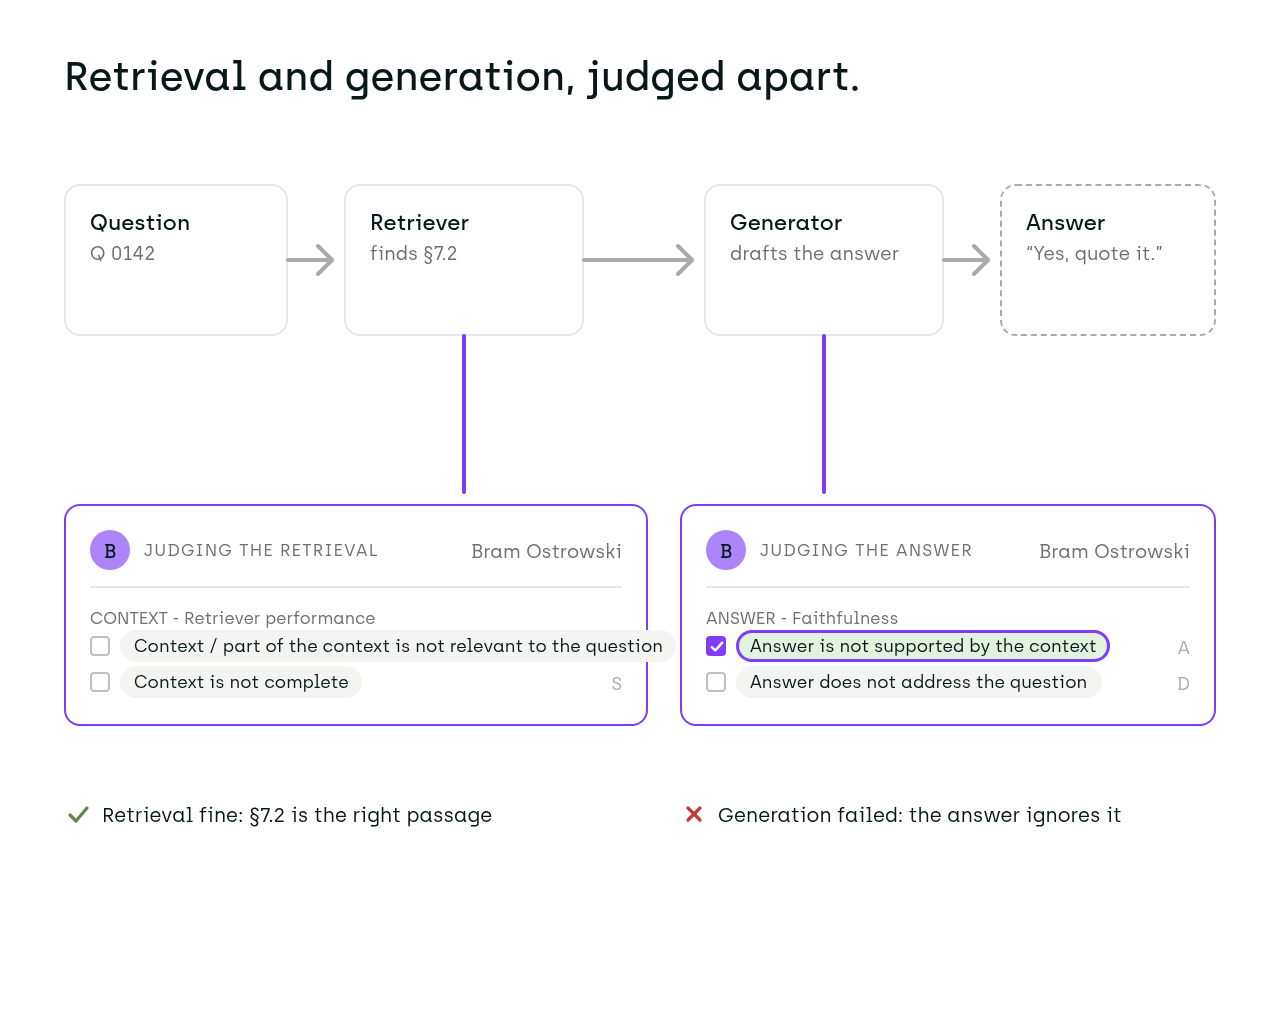
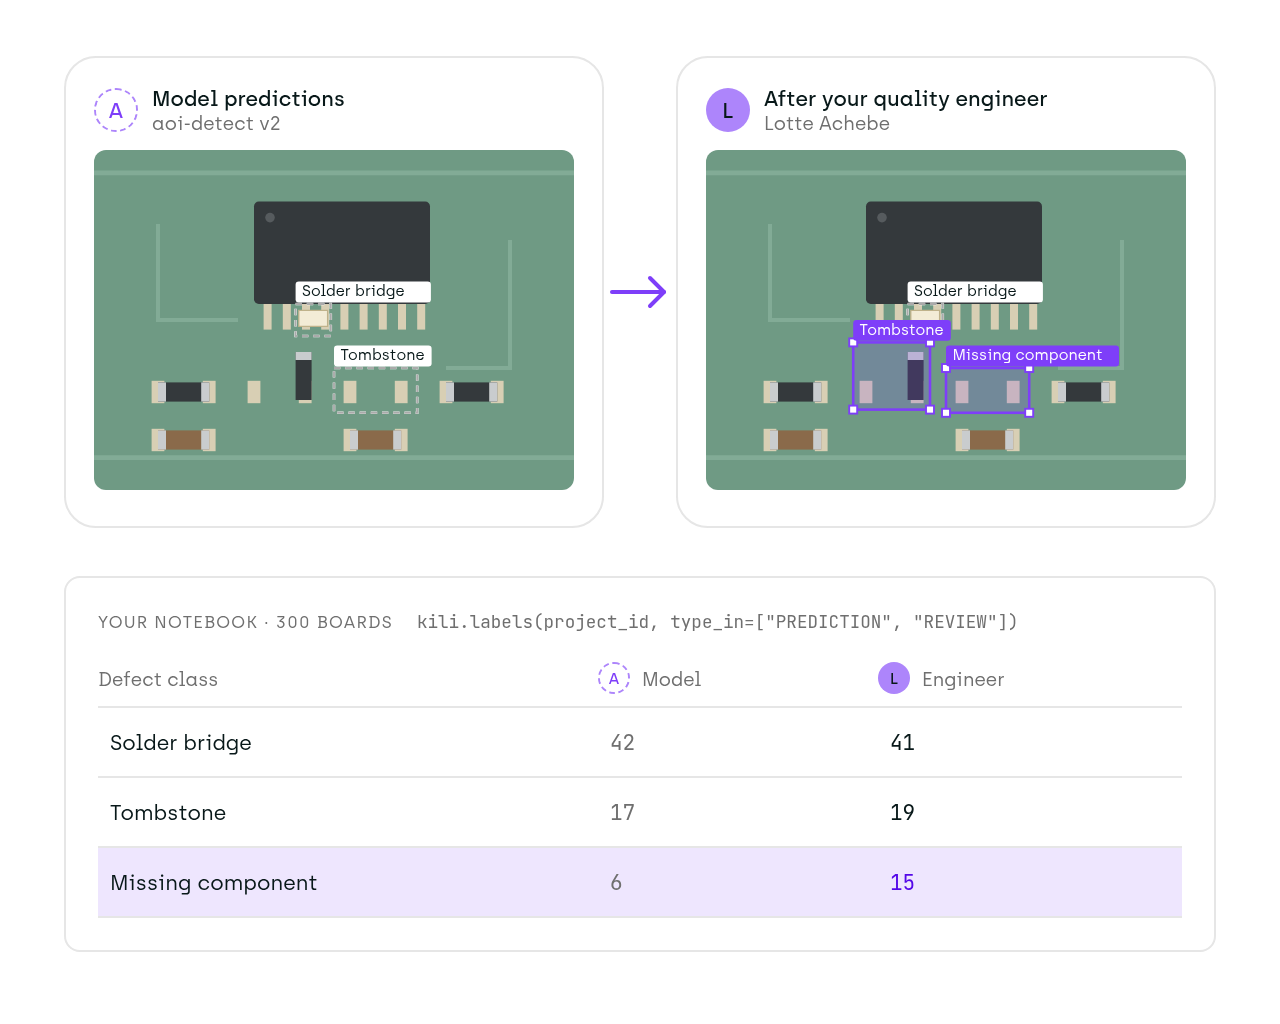
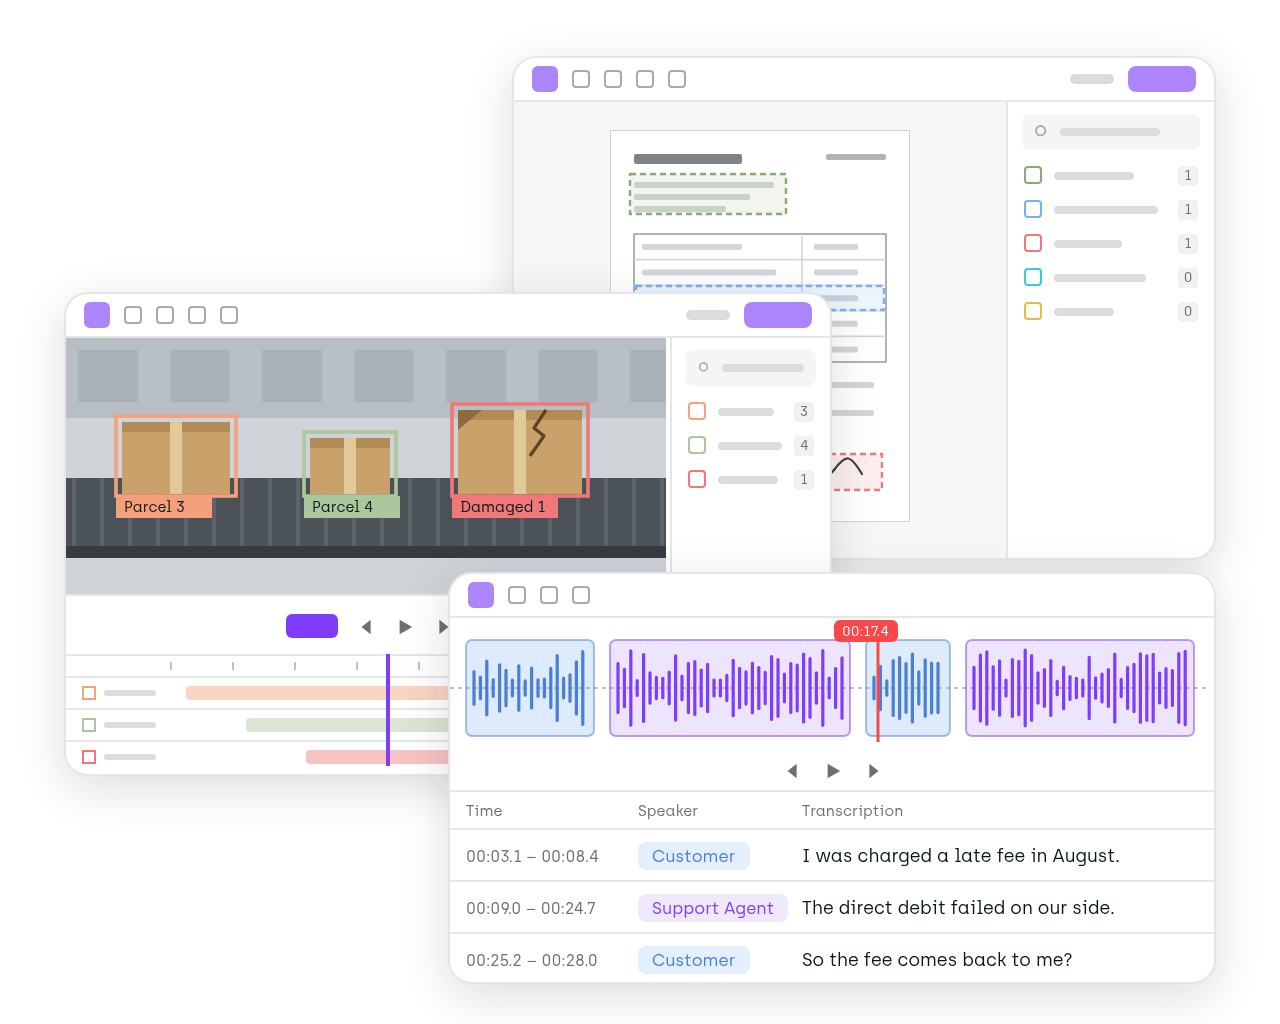
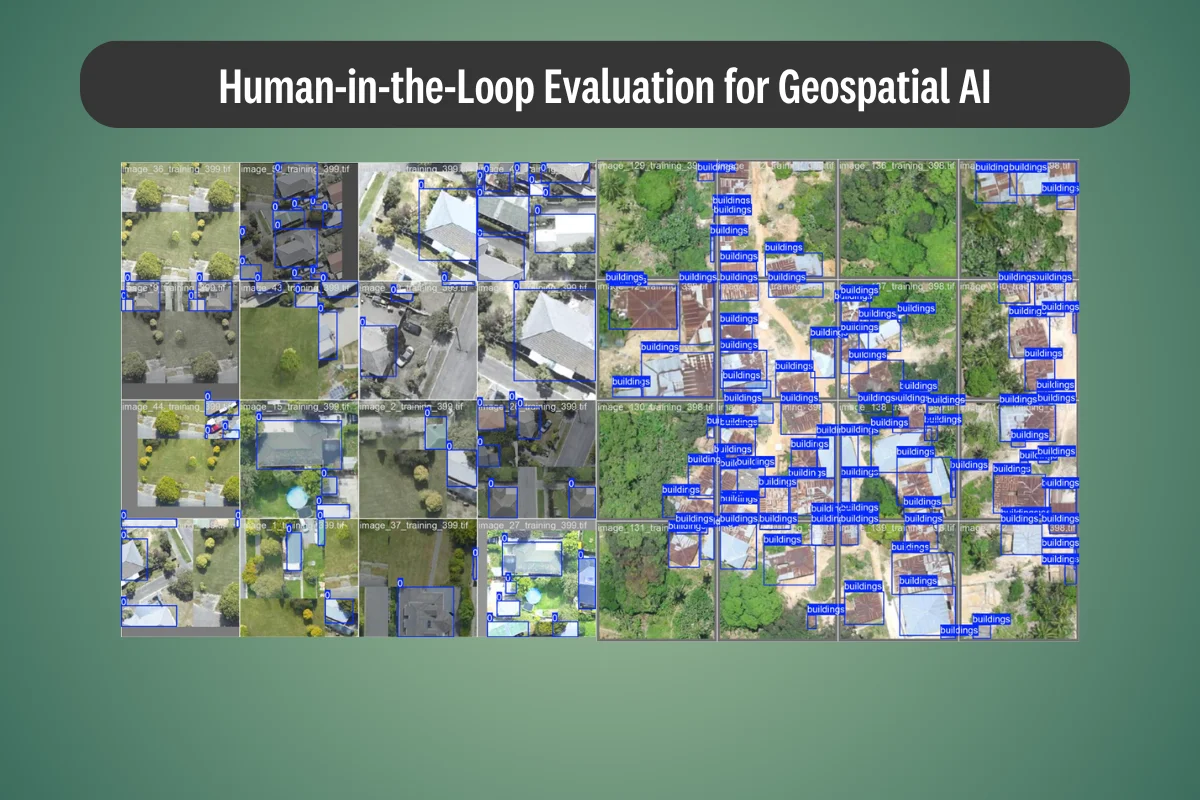
AI evaluation is the process of checking whether a model's outputs are correct, safe and usable for the job the model will actually do. Automated metrics and public benchmarks measure general ability, but they cannot tell whether an answer about a specific insurance policy, drug interaction or defect class is right. That call needs someone who holds the domain expertise. In Kili, specialists grade outputs against criteria you set up as jobs in the project's ontology, and their agreement is measured, so the verdict itself can be checked.