ImpactBench Data Story: What 48,540 Conversations and an Expert Audit Reveal About LLM Judges
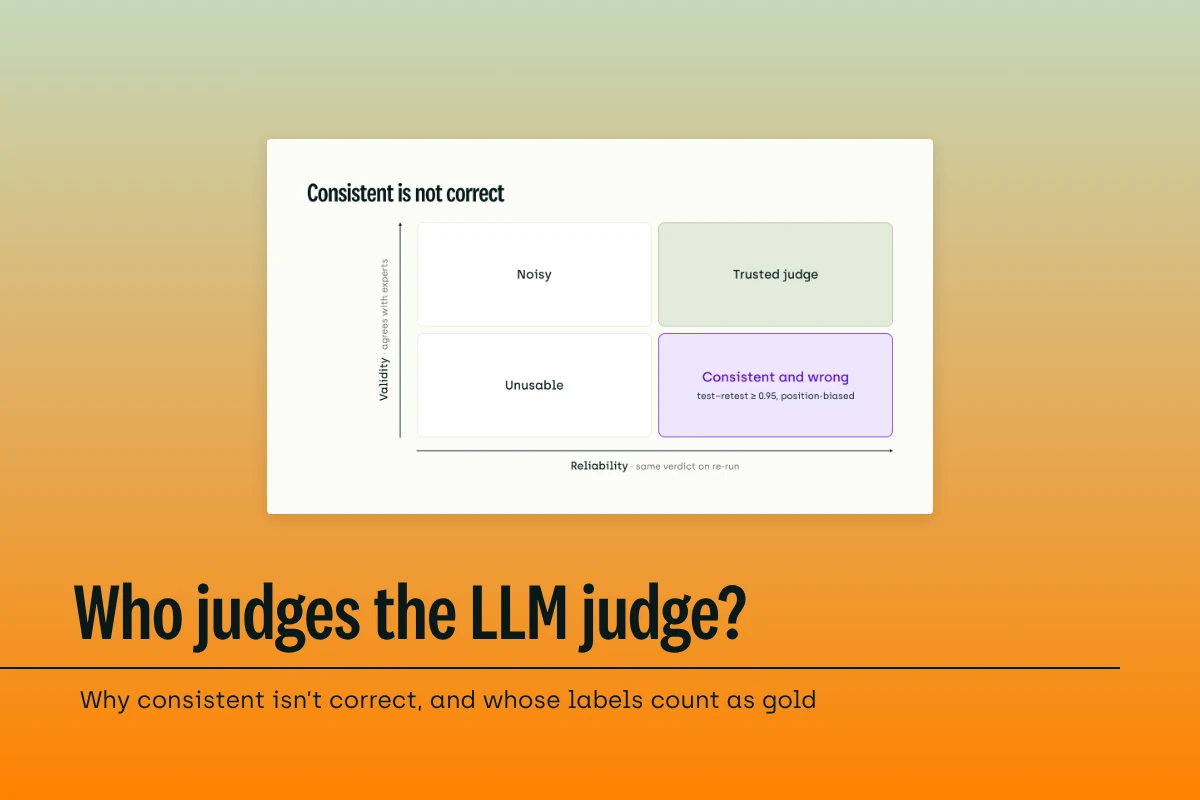
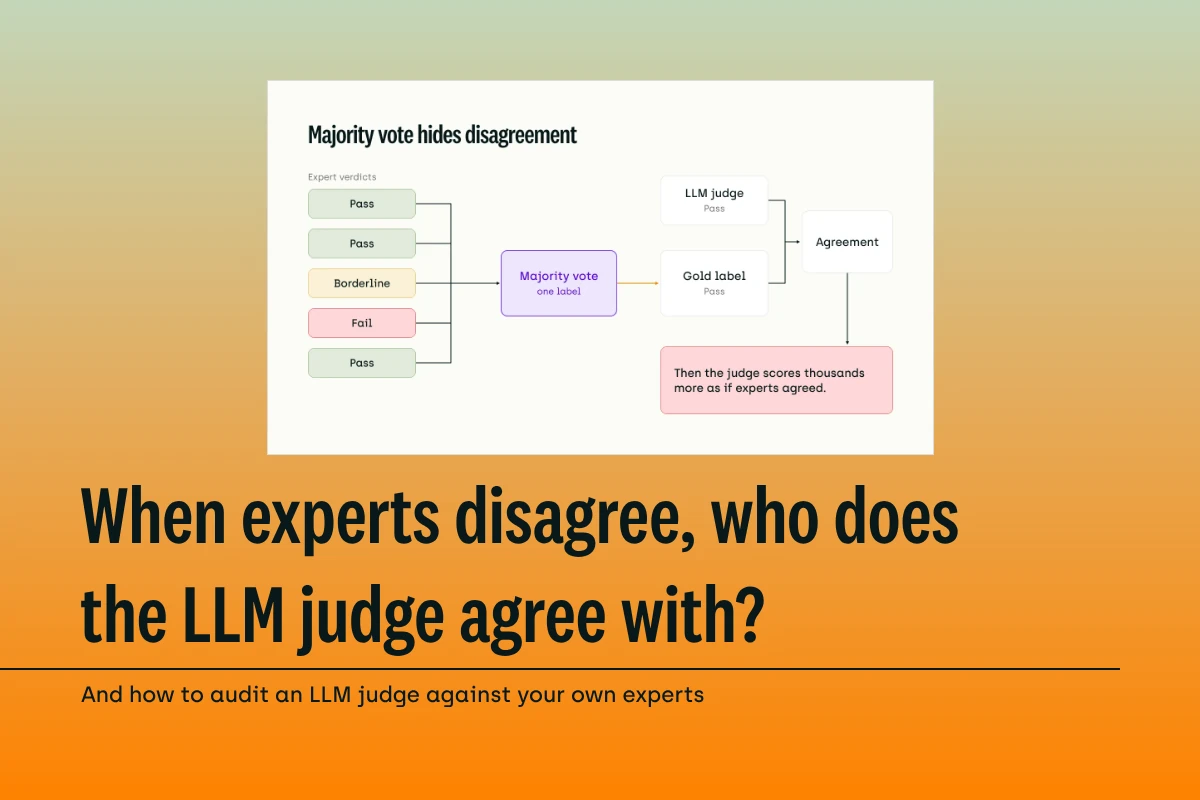
ImpactBench scored ten models on 809 expert-sourced wellbeing metrics, then had experts audit its LLM judge. Here's what the 83.3% agreement figure hides.
Learn the latest techniques to building high-quality datasets for better performing AI.
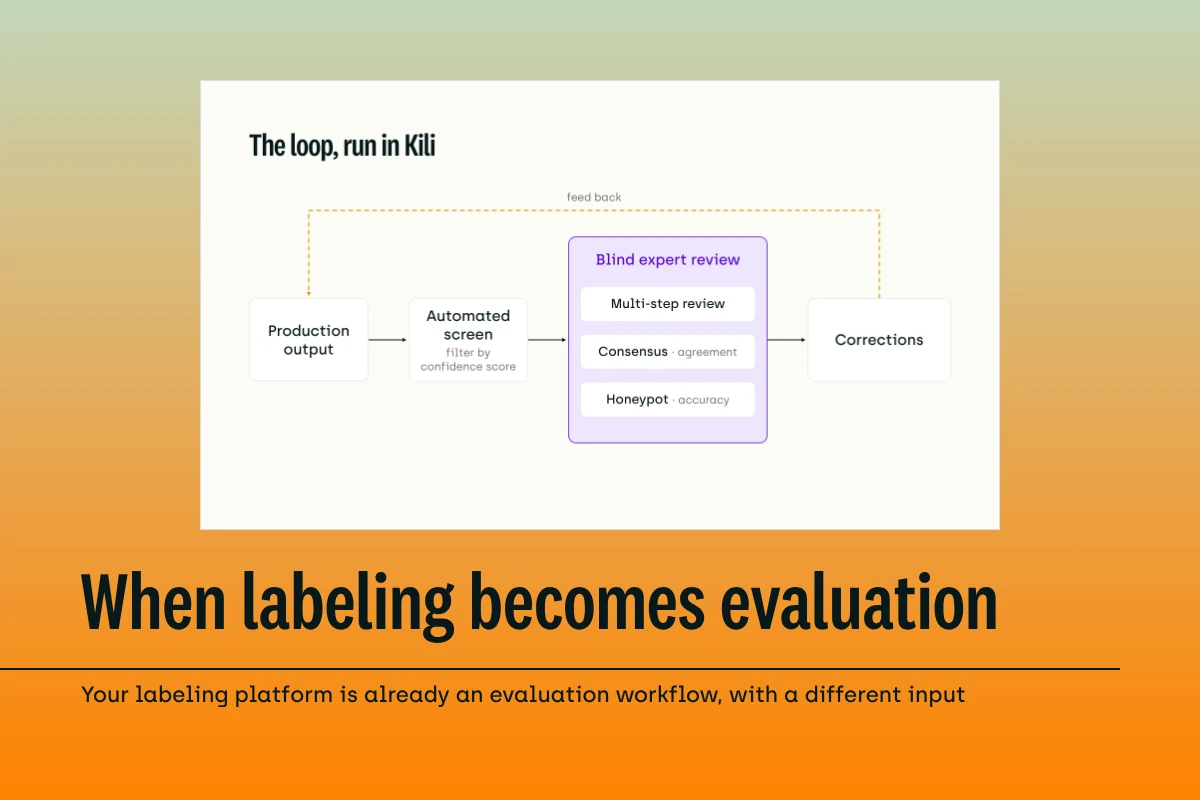
Your labeling platform is already an AI model evaluation workflow with a different input. Here is the six-step loop, and the evidence for why teams break it.
.png)

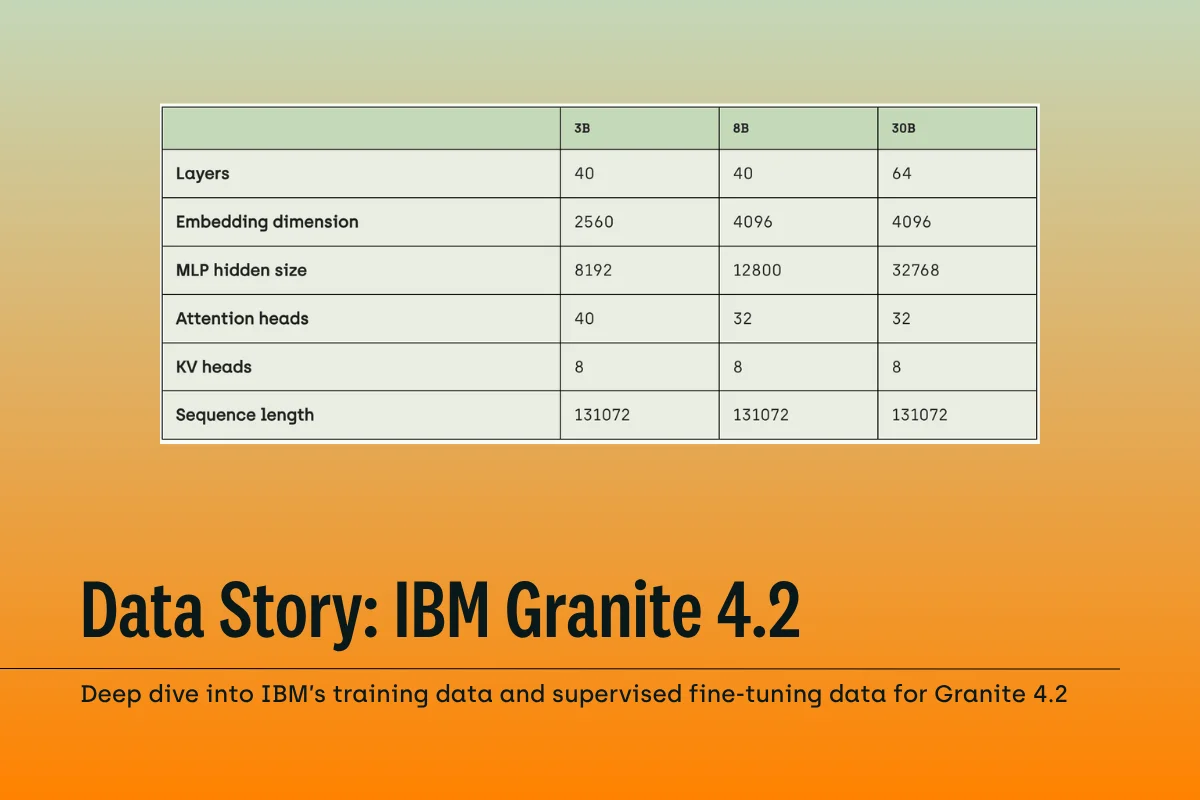
A stage-by-stage record of Granite 4.2 training data, from pretraining phases to reinforcement learning. Every figure carries the IBM document it came from.
.png)
.webp)
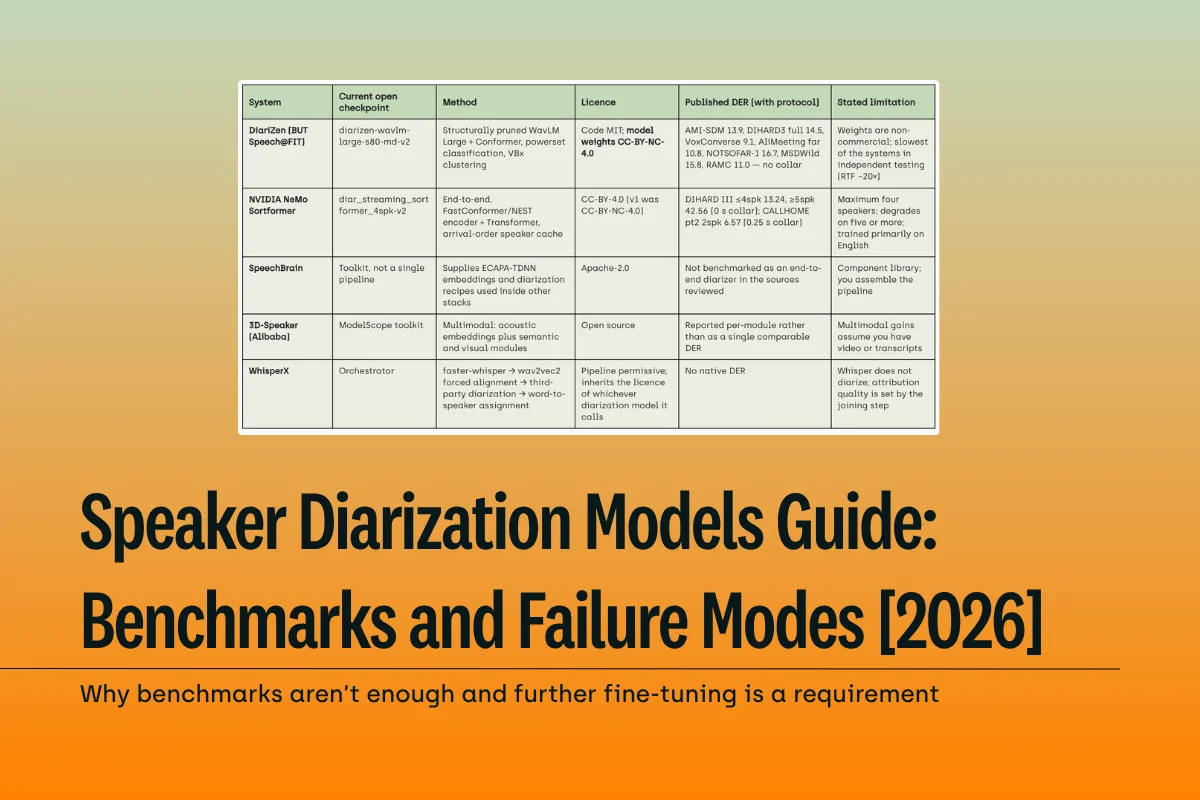
Audio annotation turns recordings into verified ground truth for speech AI. This guide covers the types, process, costs, quality control and EU AI Act rules.
.png)

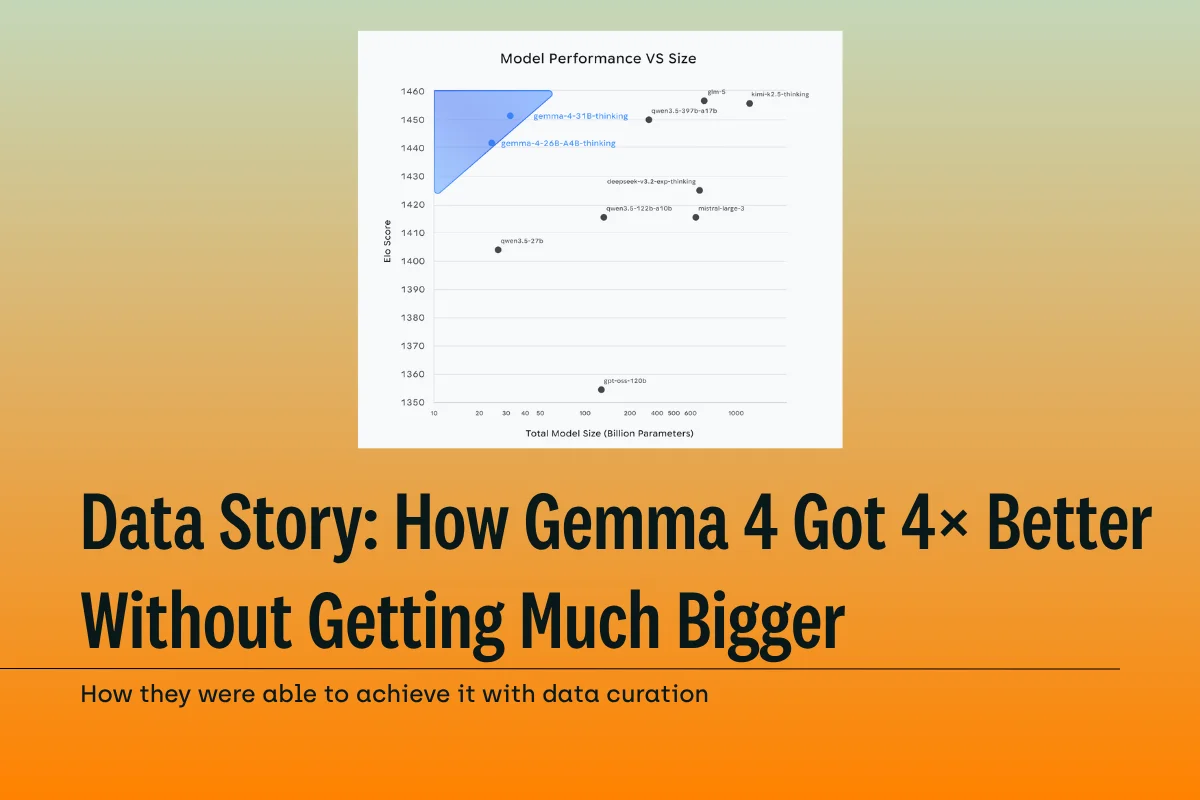
Gemma 4 added 4B parameters over Gemma 3 and quadrupled its AIME score. The technical report credits data composition for the gain, then describes its training data in two sentences.
.png)

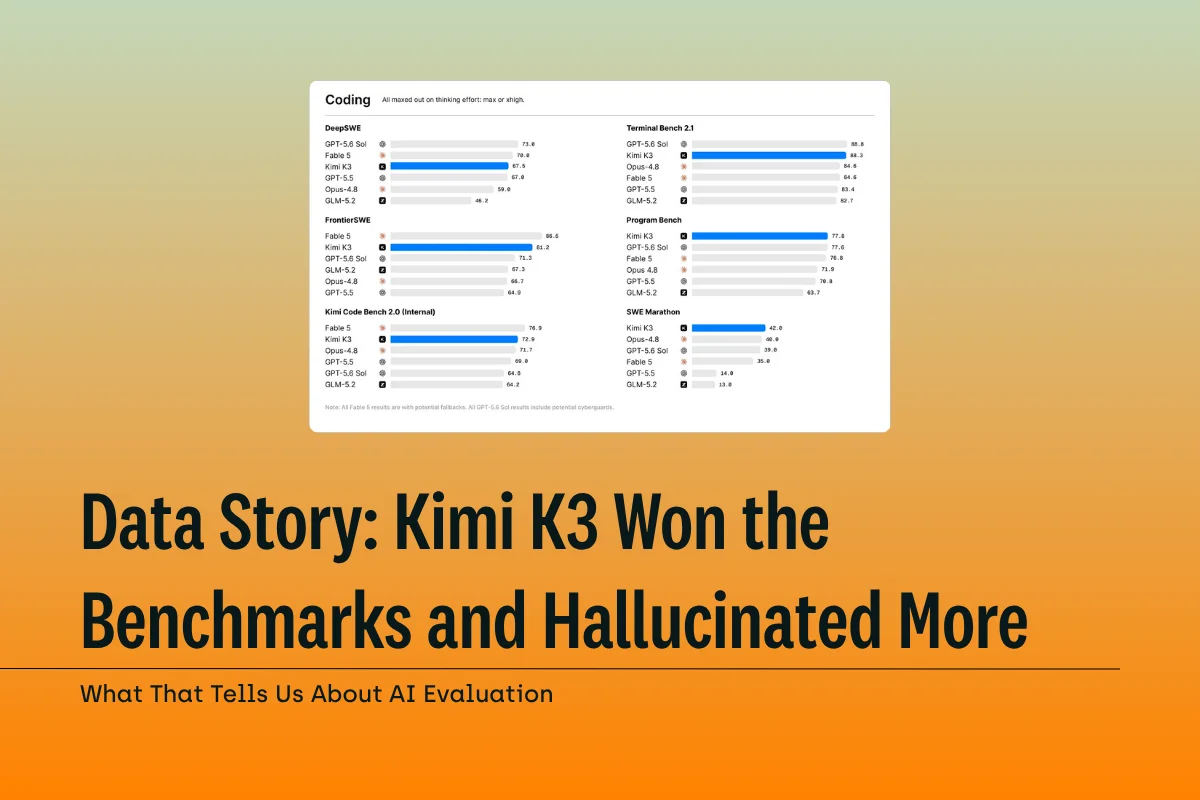
Kimi K3 ranked third on the AI Intelligence Index while its hallucination rate hit 51%. Here is what that paradox reveals about how the industry evaluates models.
.png)