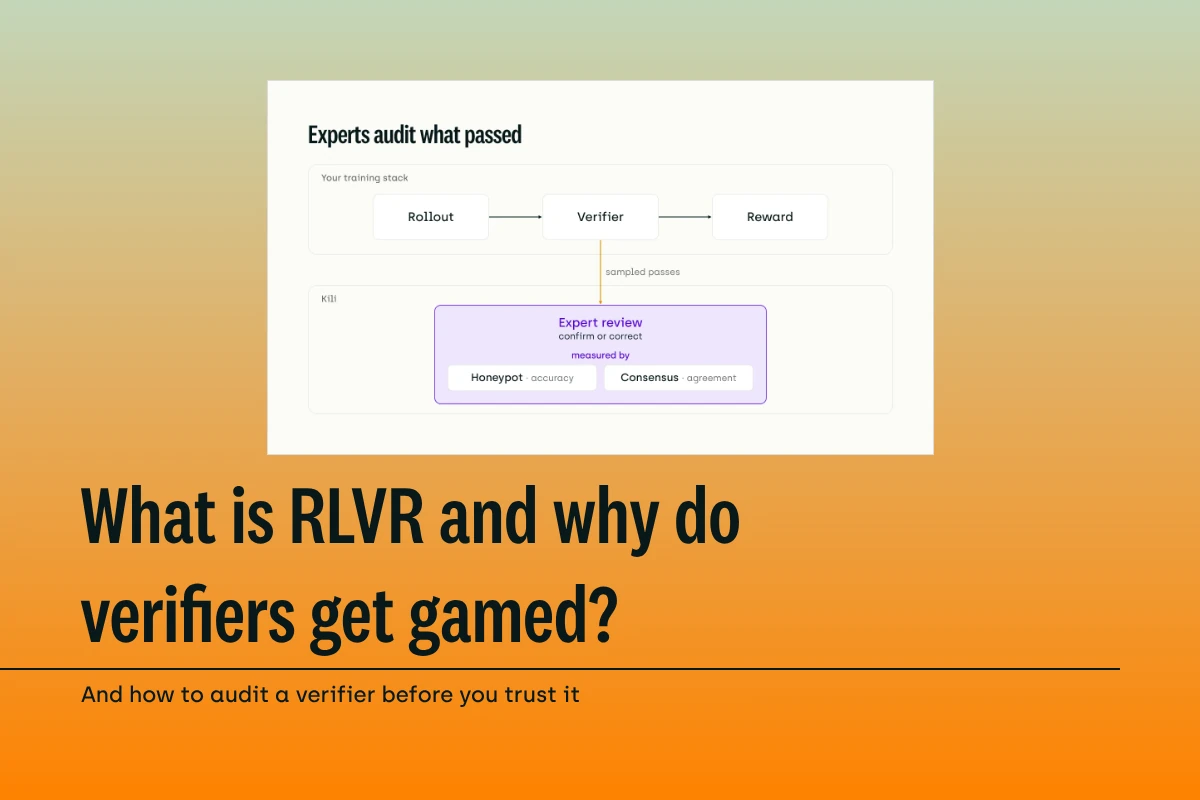
RLVR Explained: Reinforcement Learning with Verifiable Rewards, and Why Verifiers Get Gamed
RLVR trains large language models on rewards a program can check, such as a correct maths answer or a passing unit test. This guide explains how reinforcement learning with verifiable rewards works, how models learn to game the verifier, and how to audit one before you trust it.
.png)


![Fine-Tuning Audio Models Guide: What Annotation Quality Decides [2026]](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a99841bb15b6bb3d7b4c083_Audio%20Fine-Tuning%20Guide.webp)
.webp)
![Best Computer Vision Annotation Tools for On-Premise Labeling [2026] Guide](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a8ffe034889a4ba57aa64ba_Competitor%20Article%20-%20Listicle%203.webp)
![ASR Models Guide: Word Error Rate, Benchmarks and Failure Modes [2026]](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a7d8d3743d1e7bbda9ae54e_ASR%20Models.webp)
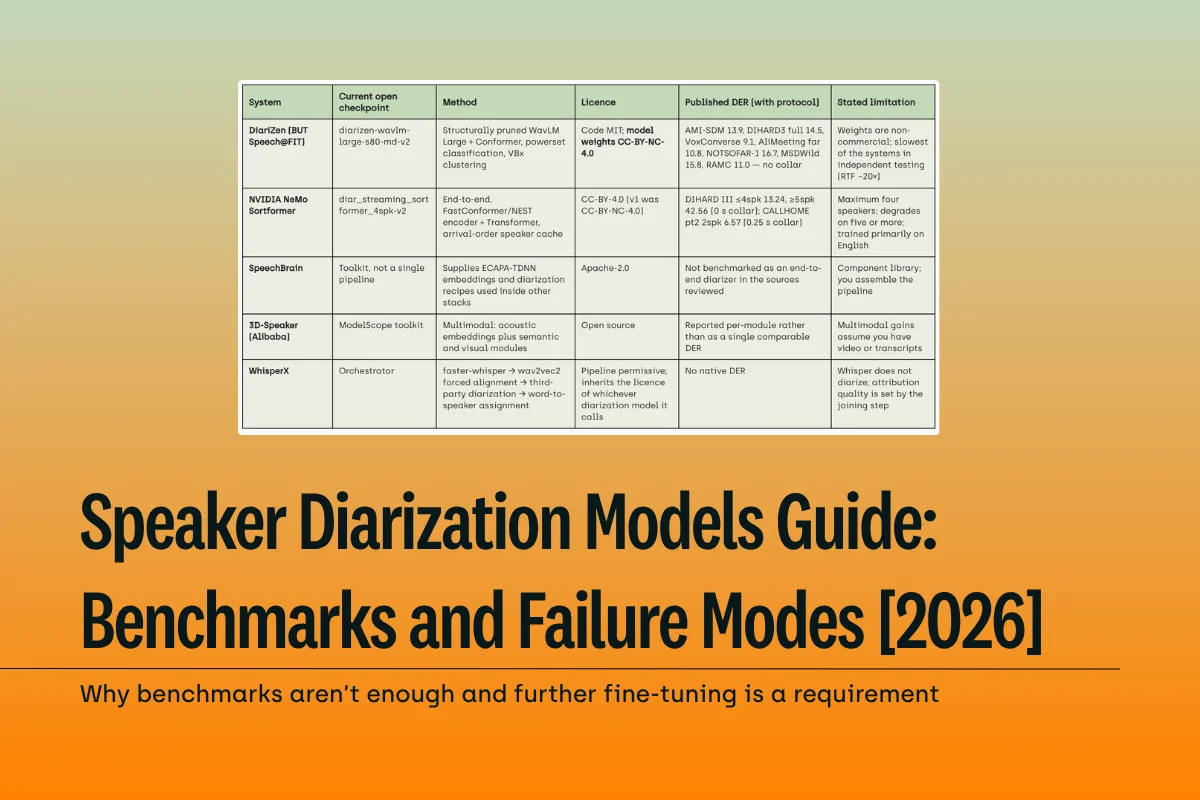
![Speaker Diarization Models Guide: Benchmarks and Failure Modes [2026]](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a7599f6a13b83298c74e35c_Speaker%20Diarization%20Models.webp)


![Best On-Premise Data Labeling Platforms for Regulated Industries [2026] Guide](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a574849a90d08dc8b9b547d_Competitor%20Article%20-%20Listicle%201%20(2).webp)