2026 RLHF Guide: What Each Post-Training Stage Asks Human Experts to Do
RLHF is now one stage in a three-stage post-training pipeline, and each stage asks people for a different kind of judgment. This guide maps SFT, preference optimisation and verifiable rewards by the human work they need, and by how each one fails when that work is weak.
.png)


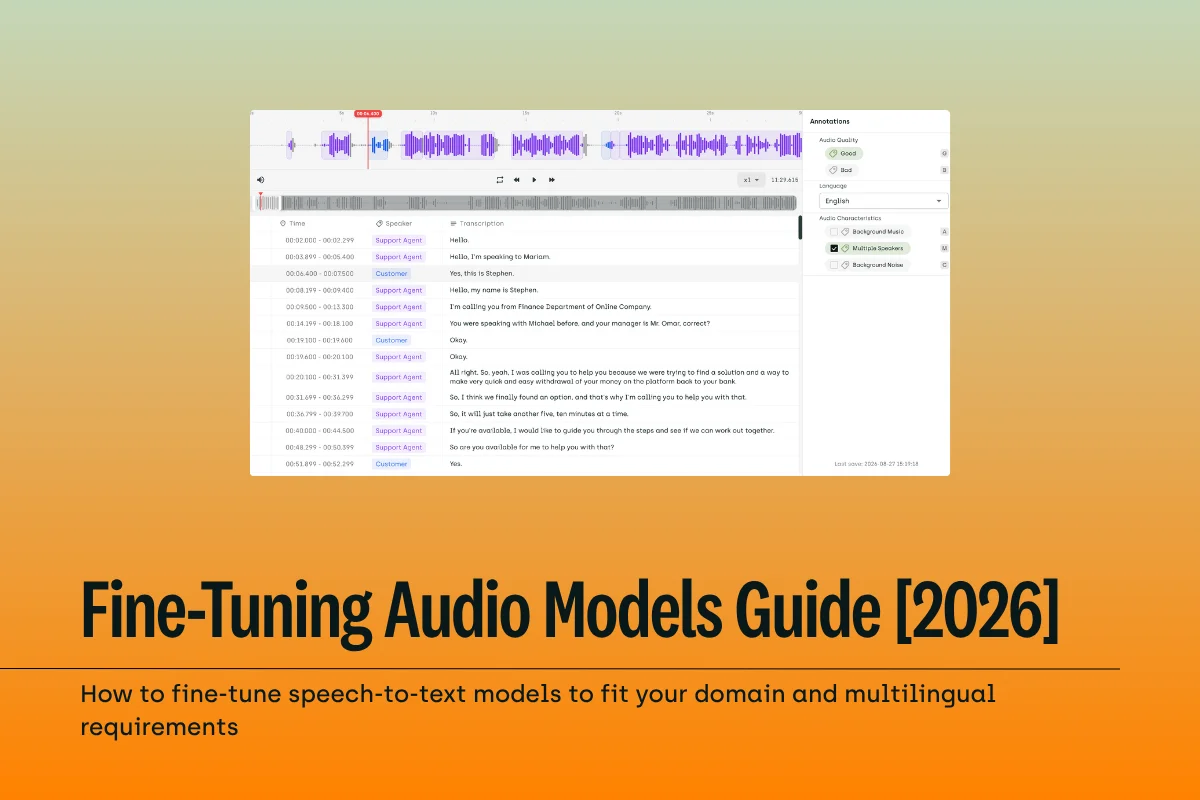
![Fine-Tuning Audio Models Guide: What Annotation Quality Decides [2026]](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a99841bb15b6bb3d7b4c083_Audio%20Fine-Tuning%20Guide.webp)
.webp)
![Best Computer Vision Annotation Tools for On-Premise Labeling [2026] Guide](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a8ffe034889a4ba57aa64ba_Competitor%20Article%20-%20Listicle%203.webp)
![ASR Models Guide: Word Error Rate, Benchmarks and Failure Modes [2026]](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a7d8d3743d1e7bbda9ae54e_ASR%20Models.webp)
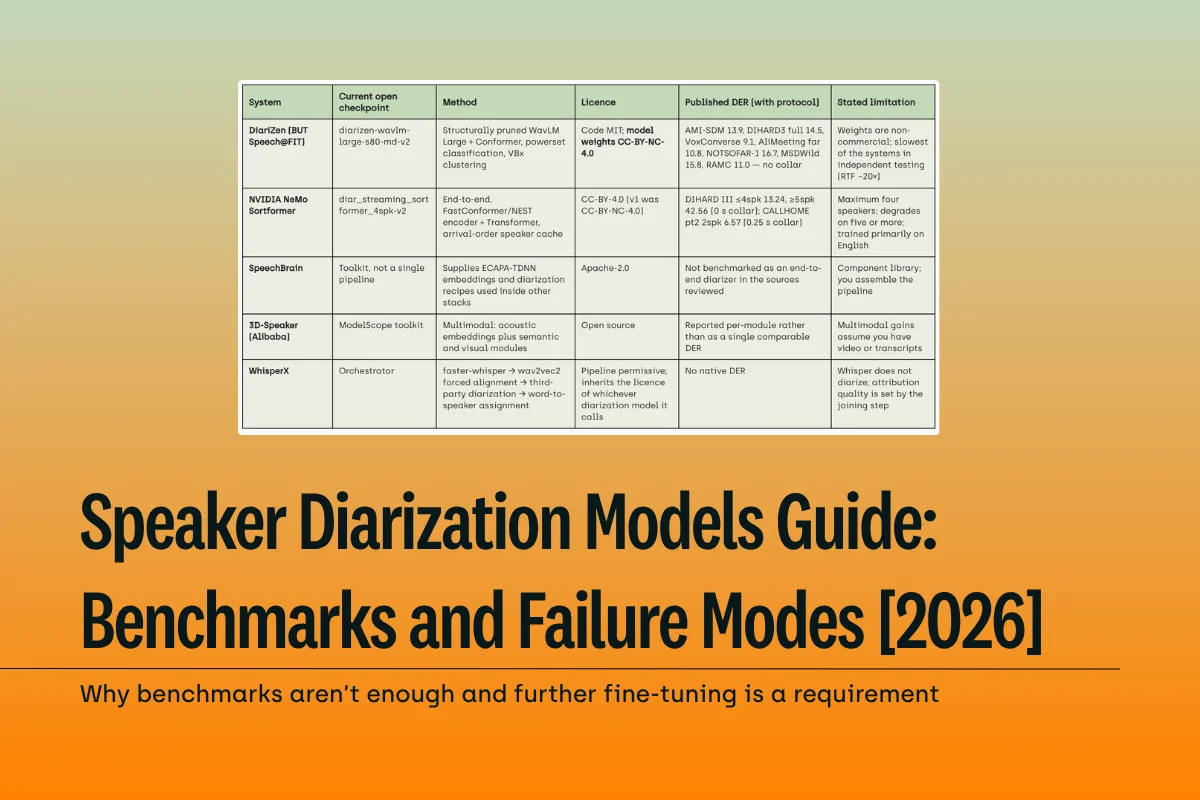
![Speaker Diarization Models Guide: Benchmarks and Failure Modes [2026]](https://cdn.prod.website-files.com/68da32b2041c593b0511a582/6a7599f6a13b83298c74e35c_Speaker%20Diarization%20Models.webp)